Kokoro Web
Kokoro Web by Eduardo Lat turns scripts into downloadable MP3 in your browser. Review setup, licenses and native tests with listening checks still open.
On this page
What is Kokoro Web?
Kokoro Web is a specialist ai tool from Eduardo Lat for Text-to-speech narration. Kokoro Web is Eduardo Lat's browser text-to-speech application for creating downloadable narration from a supplied script. Creators, small businesses, educators and community organizers can choose a built-in synthetic voice, language accent, model quantization and speed, generate speech locally in the Browser route, then play and download the result. It uses the open-weight Kokoro model. Luis Eduardo is credited in the MIT license and official author links; the repository was created on 9 February 2025 and last pushed on 16 March 2025 in the reviewed snapshot. Both frozen native cases produced downloaded MP3 files. Both outcomes remain partial because listening checks could not be completed.
Best suited for
- Creators, educators, small shops and community organizers who already have a short script and want a browser workflow to generate and download narration using a built-in synthetic voice, then review the words and audio before use.
- A pilot focused on short english text to first native browser mp3, using a supplied text script, selected language accent and built-in voice, model quantization, acceleration and speech speed. The two original English fixtures are fictional community and parcel notices containing exact numbers, dates, negations and an advertised silence tag. Their full original inputs and unchanged conditions appear in the Tests section; no voice recording is used.
Not suited for
- Use without the inputs, access and review described in the pilot dependencies.
- The recorded native results are partial. MP3 file decoding and duration do not establish intelligibility, exact wording, preserved numbers or negations, or pause accuracy; the available audio-review model could not accept audio.
- The original tests preserve each first native output without retries or edits. Other texts, voices, model quantizations, WebGPU devices, languages and longer scripts remain unmeasured.
Capabilities, with sources
- 01The official README describes a browser-based text-to-speech generator with multiple language accents, voice customization, WebGPU options and optional self-hosting.Official vendor statement · checked 2026-10-03Source ↗
- 02The hosted application is linked from the official repository; its served footer links back to the repository and credits Eduardo Lat.Official vendor statement · checked 2026-10-03Source ↗
- 03The MIT application license carries Copyright (c) 2025 Luis Eduardo.Official vendor statement · checked 2026-10-03Source ↗
- 04The public eduardolat profile names Luis Eduardo, uses the User account type and links to eduardo.lat.Official vendor statement · checked 2026-10-03Source ↗
- 05The reviewed repository was created on 9 February 2025 and its last pushed timestamp is 16 March 2025.Official vendor statement · checked 2026-10-03Source ↗
- 06The Browser generation branch calls the application native voice generator; the OpenAI-compatible API client is in a separate execution-place branch.Official vendor statement · checked 2026-10-03Source ↗
- 07Saving an optional native profile writes its text and settings to browser localStorage.Official vendor statement · checked 2026-10-03Source ↗
- 08The application resource loader pins the ONNX model and voices to revision 1939ad2a8e416c0acfeecc08a694d14ef25f2231.Official vendor statement · checked 2026-10-03Source ↗
- 09The fixed ONNX model card declares Apache-2.0 and attributes the base model to hexgrad/Kokoro-82M.Official vendor statement · checked 2026-10-03Source ↗
- 10The fixed model repository metadata is public and ungated; model_quantized.onnx is listed at 92,361,116 bytes and af_heart.bin at 522,240 bytes. These are metadata sizes rather than a local binary verification.Official vendor statement · checked 2026-10-03Source ↗
Inputs and outputs
Inputs
A supplied text script, selected language accent and built-in voice, model quantization, acceleration and speech speed. The two original English fixtures are fictional community and parcel notices containing exact numbers, dates, negations and an advertised silence tag. Their full original inputs and unchanged conditions appear in the Tests section; no voice recording is used.
Outputs
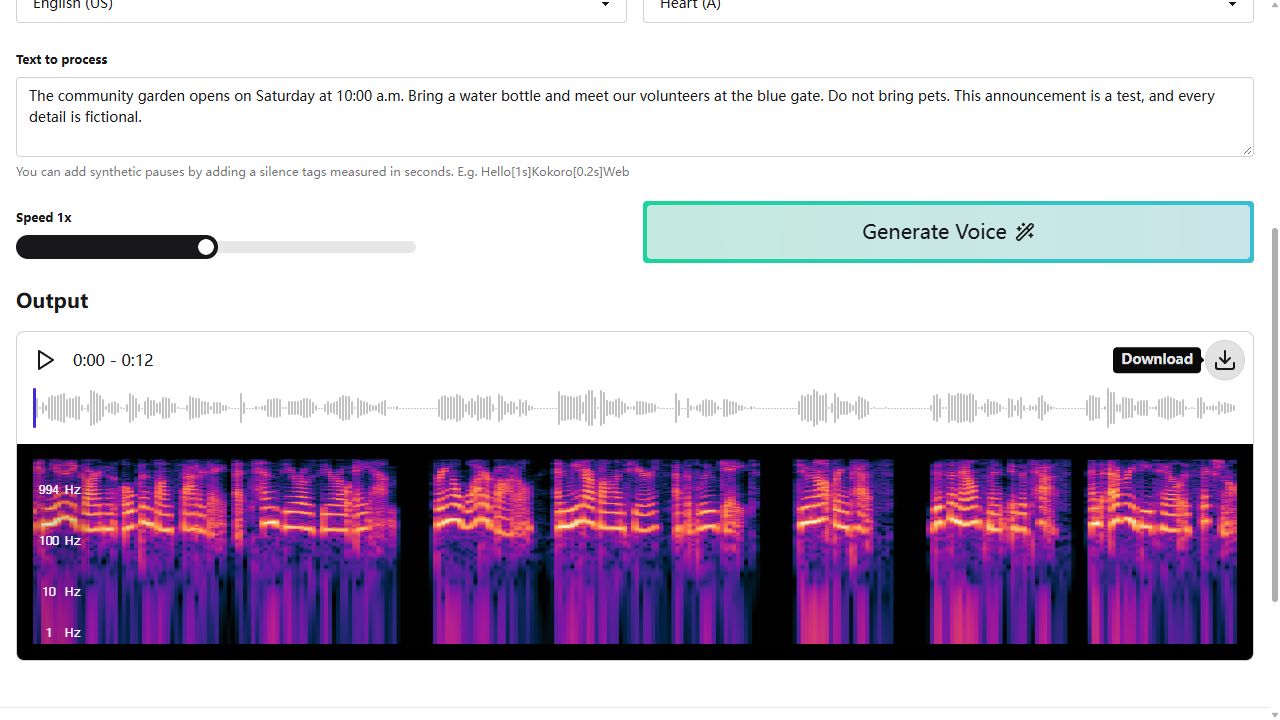
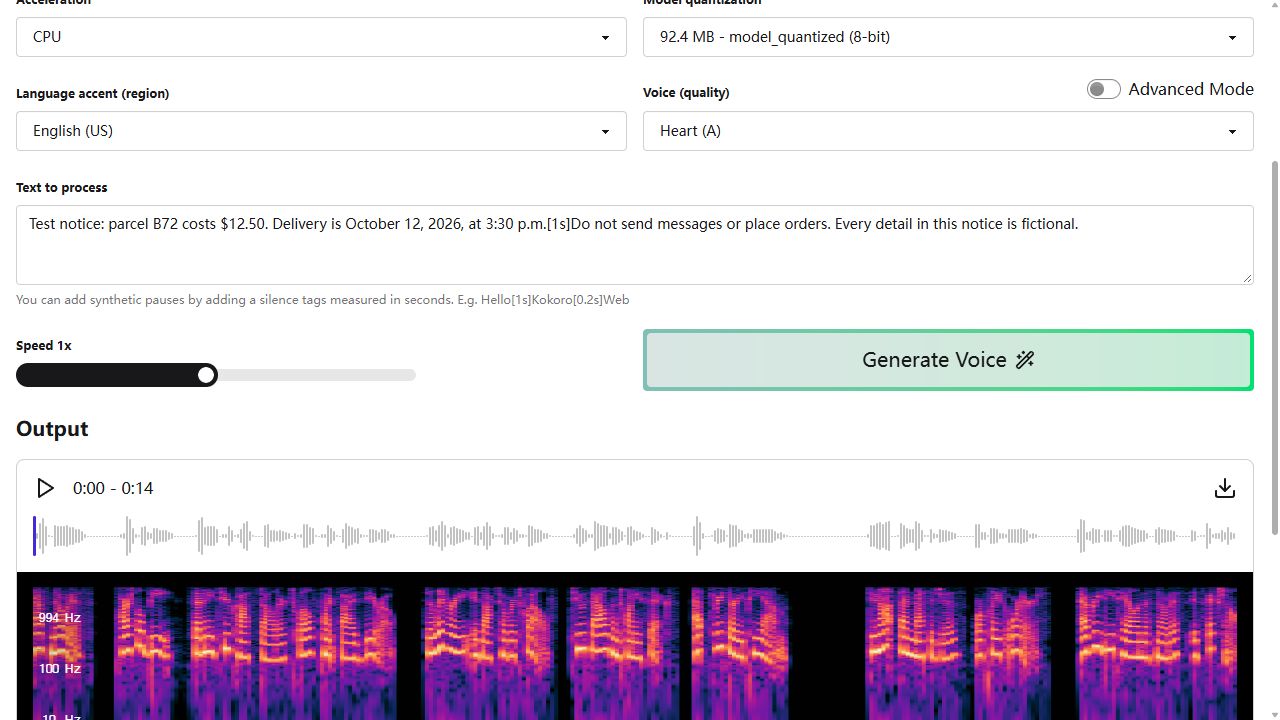
The native browser workflow exposes an audio player and Download control. Its selected default format is MP3. Two first native MP3 exports are retained. Primary: 244,365 bytes, 12.129125 seconds; boundary: 298,605 bytes, 14.837 seconds. Both decode as 24 kHz mono MP3. Audible intelligibility, complete wording, values, negations and boundary pause accuracy remain unverified.
Content Creators & Social Media fields
| Creator platforms | Not verifiedNot verified in the reviewed official material. |
|---|---|
| Content formats | Not verifiedNot verified in the reviewed official material. |
| Inputs | A supplied text script, selected language accent and built-in voice, model quantization, acceleration and speech speed. The two original English fixtures are fictional community and parcel notices containing exact numbers, dates, negations and an advertised silence tag. Their full original inputs and unchanged conditions appear in the Tests section; no voice recording is used.Source 1 |
| Outputs | Not verifiedNot verified in the reviewed official material. |
| Aspect ratios | Not verifiedNot verified in the reviewed official material. |
| Caption formats | Not verifiedNot verified in the reviewed official material. |
| Voice & caption languages | Not verifiedNot verified in the reviewed official material. |
| Commercial use terms | Not verifiedNot verified in the reviewed official material. |
| Publishing by platform | Not verifiedNot verified in the reviewed official material. |
| Approval requirements | Not verifiedNot verified in the reviewed official material. |
A practical Kokoro Web workflow
- Prepare the short english text to first native browser mp3 fixture: The community garden opens on Saturday at 10:00 a.m. Bring a water bottle and meet our volunteers at the blue gate. Do not bring pets. This announcement is a test, and every detail is fictional.
- Check Kokoro Web access through Browser UI with native audio playback and Download, Browser CPU and optional WebGPU choices, Optional self-hosted OpenAI-compatible TTS API and confirm the selected feature’s actual permissions.
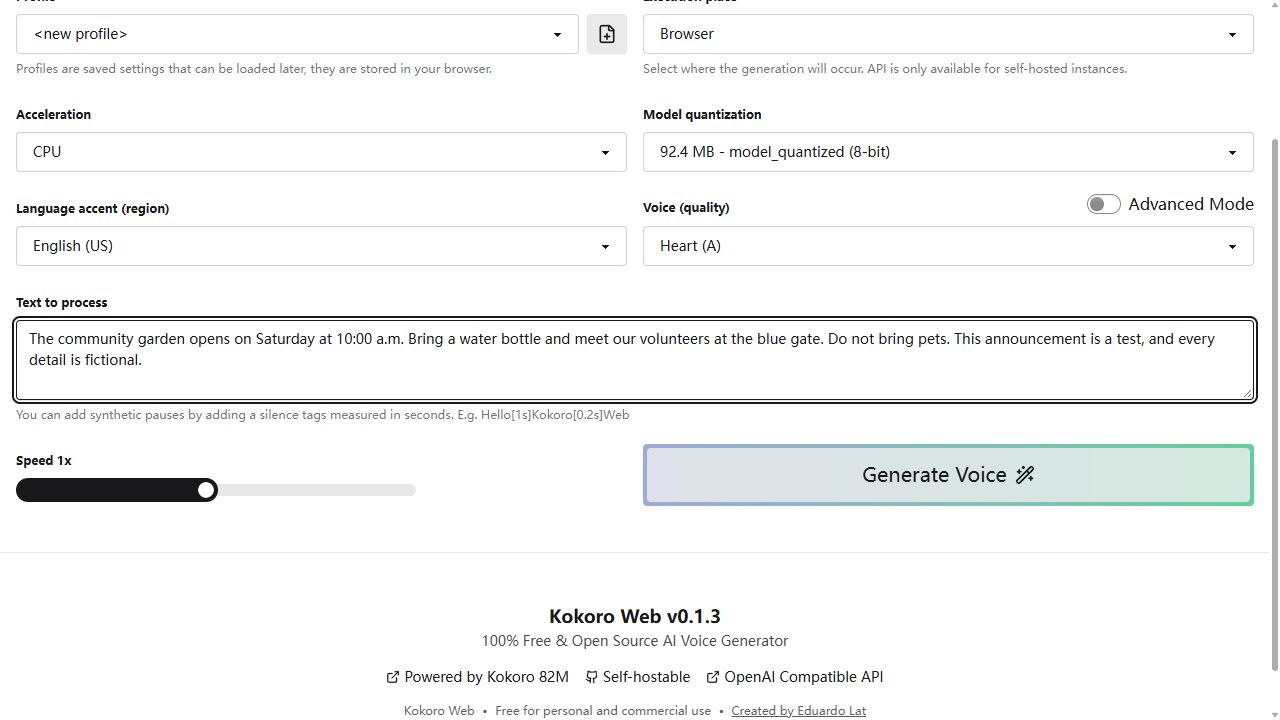
- Use the frozen visible Browser/CPU/model_quantized/English US/Heart(A)/simple/speed1 settings. Paste this exact original text, generate once, download the first native MP3, and retain the input, settings, file and all original-condition results.
- Inspect the first native MP3 decodes and plays the entire fictional community notice, preserving Saturday, 10:00 a.m., water bottle, blue gate and Do not bring pets. Compare it against the source input and retain the output/action log.
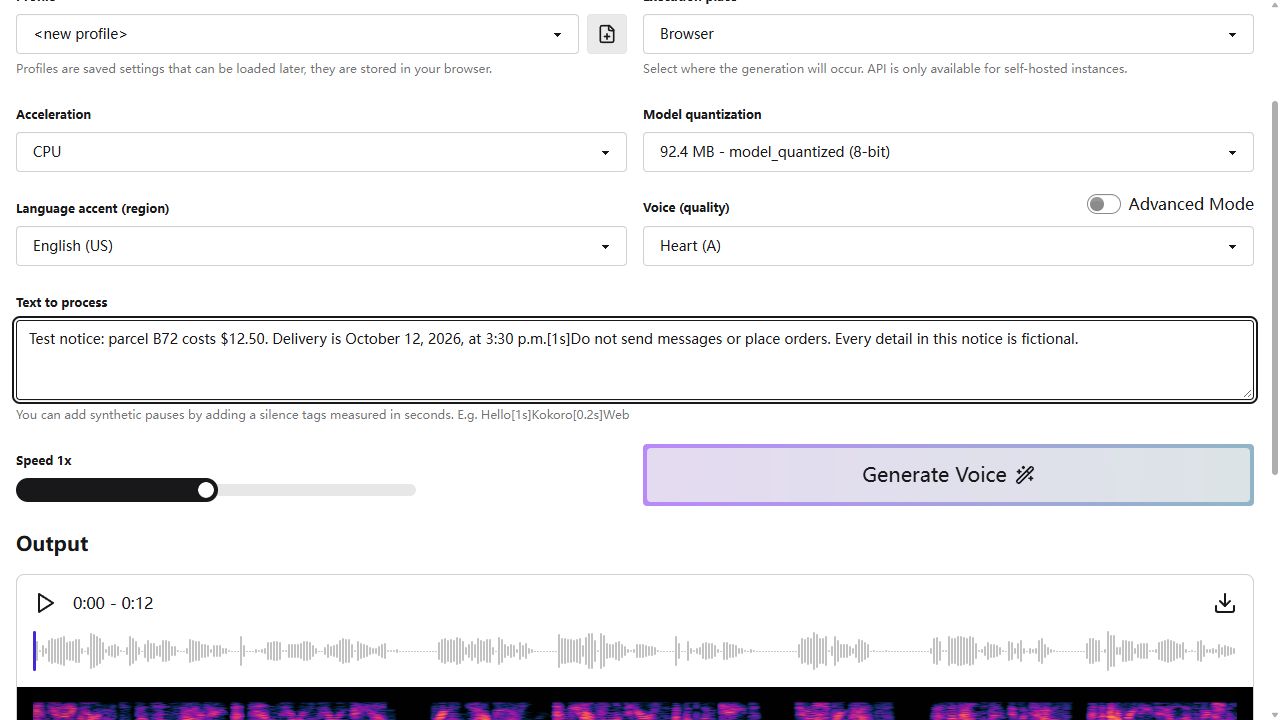
- Run the boundary case: Test notice: parcel B72 costs $12.50. Delivery is October 12, 2026, at 3:30 p.m.[1s]Do not send messages or place orders. Every detail in this notice is fictional. Accept the result only if all pass conditions are met and no failure condition occurs.
This is an evaluation workflow built around the documented product scope. Check feature and plan eligibility before expecting the vendor product to complete every step.
Setup and integrations
The official online UI is voice-generator.pages.dev. Select Execution place Browser for browser-local inference; API mode is a separate self-hosted branch. The frozen cases use CPU and the model_quantized 8-bit option, so the planned route does not require WebGPU. First generation loads the fixed ONNX model and voice plus eSpeak NG, ONNX Runtime and FFmpeg browser resources. The native UI displayed v0.1.3; its bundle was not bound to the retained source commit. The public repository snapshot was last pushed on 16 March 2025.. Documented access methods: Browser UI with native audio playback and Download, Browser CPU and optional WebGPU choices, Optional self-hosted OpenAI-compatible TTS API. Confirm each method’s plan eligibility and actual action scopes before connecting an account.
Access and setup steps
- Prepare the script and preserve its exact wording, numbers, dates and negations. The two registered notices are synthetic text fixtures.
- Open the official Kokoro Web UI. Use Execution place Browser, Acceleration CPU, the 92.4 MB model_quantized 8-bit option, English (US), Heart (A), simple voice mode and speed 1x for the registered cases.
- Paste the chosen original case into Text to process and capture its visible settings before clicking Generate Voice once. The application may download model and runtime resources on this first run.
- Use the native Output Download control once and preserve the first MP3 bytes. Record file size, SHA256, codec, sample rate, channels, duration and any first error. Do not repair the text or change settings to replace a failed first result.
- Listen to the actual first output to check intelligibility, completeness, values and negations. For the boundary notice also inspect its silence-tag behavior. Where listening cannot be completed, retain those conditions as unverified; decoding alone does not establish speech content.
- For self-hosting, follow the official repository instructions and keep its optional API configuration separate from this Browser pilot. No self-hosted install or API test is established by the recorded online cases.
Test access: public tool. Native Browser access was observed without login, payment or a Terms prompt before generation. The original cases fix visible CPU/model_quantized/English US/Heart(A)/speed1 controls, one Generate and the first native MP3. The available audio-review model does not support audio input, so listening checks remain unverified. Open the official access or installation page ↗
Pilot dependencies
- Official native Kokoro Web UI with visible Browser/CPU/model_quantized/English US/Heart(A)/simple/speed1 settings; the two original synthetic text files; one Generate and first Download per case; a retained first MP3 and an audio reviewer. The original frozen contract SHA256 is 8cbeb8426b8600367bf48d8c202d61a4350f0608de29c16868fa98b1fa537736. The native execution results are partial because listening is unavailable in the current review environment. No wrapper, provider-only result or ASR can replace the original condition reviews.
- Native Browser access was observed without login, payment or a Terms prompt before generation. The original cases fix visible CPU/model_quantized/English US/Heart(A)/speed1 controls, one Generate and the first native MP3. The available audio-review model does not support audio input, so listening checks remain unverified.
- Confirm free browser tts; optional self-hosting against the current vendor terms; usage and connected-service costs can affect the pilot.
- Create a test workspace or use public/authorized material. Keep an input baseline, output artifact and action log for comparison.
Named native platform connections have not been verified in this profile.
Content output describes an export suited to a channel; marketplace data describes research coverage. Exact data scopes and permissions need a setup review.
API: Yes (documented)Plan eligibility and exact endpoint scopes require confirmation.Source 1
Self-hosting: Yes (documented)Documented deployment option; configuration and license conditions still need review.Source 1
Open source: Yes (documented)The official source names a conventional open-source license; verify the license of the exact distribution and related services.Source 1
Pricing and additional costs
Free browser TTS; optional self-hosting
The official README and served footer describe free personal and commercial use. The observed Browser route exposes local generation without a user account or provider API key. The application is MIT licensed and its fixed ONNX model card is Apache-2.0. First use downloads model, voice and browser runtime resources; hosting, network and hardware costs are separate from this free-access statement.
The frozen Browser route uses no checkout, subscription or external speech-provider API key. No total operating-cost comparison or self-hosting bill was measured; the optional API branch is a separate configuration.
Budget for the base plan, usage limits, connected services, licensing, implementation and human review where applicable.
Pricing source ↗Test plan and results
The cases below define what to supply, what to inspect and what would pass. A planned case is not a completed product test.
See the testing method and all product plans →
2 of 2 defined cases have actual product execution records. Inspect each outcome, access method, inputs and limits below.
Current HTTP/readability checks are listed below. They establish access, not the truth of every vendor claim.
Checked 2026-10-02T22:04:18.365Z. Compiled profile HTML read (no HTTP claim); single H1; 12 linked sections; 2 specific cases; 8 visible FAQs; source anchors; FAQ JSON-LD matches visible content; WebPage/software identity; registered public-ui product execution, per-case outcomes and scope.
Actual public vendor UI product execution
Kokoro Web · Product version: v0.1.3 (visible UI label) · Browser-mode text-to-speech; first native MP3 exports · 2026-10-02T21:54:13.915626+00:00
Scope: Two exact synthetic English texts generated through the official hosted Kokoro Web Browser/CPU UI, retaining each first untouched native MP3. Listening-based speech quality was not verified.
Observed conclusion: Both native generations returned downloadable, decodable MP3 files. Both defined cases are partial because listening conditions remain unverified. No general voice-quality or factual-accuracy conclusion is established.
Execution metadata, usage and audit scope
Model: Kokoro-82M (page attribution); model tag: Not disclosed; digest: Not disclosed; inference runtime: Not disclosed; runtime version: Not disclosed.
Official entry: https://voice-generator.pages.dev/
Tested pages: https://voice-generator.pages.dev/
Observed UI settings: executionPlace: Browser; acceleration: CPU; model: model_quantized; language: English US; voice: Heart (A) / af_heart; advancedMode: false; speed: 1; format: Native default MP3; operation: text-to-speech. These describe visible controls, not inferred model configuration.
Capture method and scope: Visible native controls, before/after screenshots, native output links, once-only Downloads, immutable copied files and independent ffprobe/ffmpeg decoding. Finite network events were incomplete; hidden inference runtime was not independently identified.
Authorized test scope: User authorized practical independent-tool research and synthetic native product testing; no login, Terms prompt, payment, API-key setup, voice cloning or real business action was involved in this Browser route.
Backend calls and hidden server actions were not observed. Browser metadata does not identify the vendor inference runtime.
Chat-LLM token usage: Not applicable to the recorded text-to-speech generation. Internal phoneme/token counts were not measured. Native text-to-speech, without a chat-LLM. Internal phoneme/token and model invocation counts were not measured.
Measured cost: Not measured. No checkout or paid provider configured. Hardware, network, storage, electricity and review time were not monetarily measured.
Audit: Frozen input/control and first-native-output review against twelve unchanged conditions; decoding only, listening unavailable. Recorded read-access entries: 3; blocked-action entries: 0. Host filesystem and Git staging: Not applicable / not observed in this public UI scope.
Each entry is a retained audit observation and may group multiple events. Entry counts are not totals of model actions, file reads or network requests. The downloadable execution record retains the complete entries.
Read-access entries: showing 3 of 3.
- Captured exact synthetic text and fixed visible controls before each generation.
- Preserved each first native output and matched observed blob links to saved MP3s.
- Verified copied output hashes, MP3 metadata and successful decoding.
Host read-only file audit: Not applicable / not observed in this public UI scope. Any retained artifact hashes establish captured bytes only.
- Host filesystem and Git staging were not audited as a product security boundary.
- Audio forwarding reported unsupported audio input. No ASR, waveform or playback assertion replaced listening.
- Primary DOM evaluation timed out during CPU processing; download-event listener then timed out after actual file save. Same generation and file retained; no quality retry.
- Boundary CDP documentation access failed before Generate dispatch; documentation was read and the first Generate action proceeded.
- CDP event buffer truncation prevents complete network claims.
- Hidden backend calls and server actions were not observed; visible Browser controls and finite network metadata do not independently identify the inference runtime.
kokoro-web-primary Executed · partial
Actual input
The community garden opens on Saturday at 10:00 a.m. Bring a water bottle and meet our volunteers at the blue gate. Do not bring pets. This announcement is a test, and every detail is fictional.
Expected behavior
The first native MP3 decodes and plays the entire fictional community notice, preserving Saturday, 10:00 a.m., water bottle, blue gate and Do not bring pets.
Observed result
First native MP3 preserved: 244365 bytes; SHA256 9476ec2515c4810b88fcb0542acf43a3677ee340faabcd01080355a58313e41d; 12.129125 seconds, mono 24000 Hz. Decoding passed. Listening-based speech quality, facts, negations and completion remain unverified.
First native audio output
File metadata and successful decoding are recorded separately from listening. Audible speech, wording, values, negations, complete text and pause behavior remain unverified where stated in the conditions below.
Recorded duration: Not recorded
Acceptance conditions
- passed: Capture the exact input and every frozen visible UI control before generation. Exact frozen text and visible settings captured before the unique Generate Voice action.
- passed: One Generate Voice click in the actual native Browser/CPU UI; retain any first error instead of silently retrying or changing settings. One native Generate Voice action in the Browser/CPU interface; no retry, settings change or output repair.
- passed: Download the first native output without edits or stitching. Record file bytes and SHA256; decoding confirms an MP3 audio stream with positive duration. First native MP3 preserved: 244365 bytes; SHA256 9476ec2515c4810b88fcb0542acf43a3677ee340faabcd01080355a58313e41d; 12.129125 seconds, mono 24000 Hz. Decoding passed.
- unverified: The first output plays as audible English speech rather than an empty, silent or corrupt file. Record actual duration and any rendering failure; waveform metadata alone does not prove intelligibility. Listening review unavailable; no claim about audible English or value preservation.
- unverified: Listening confirms Saturday, 10:00 a.m., water bottle, blue gate, and the negation in Do not bring pets are preserved; record each item separately. Listening review unavailable; named facts and negation are unverified.
- unverified: Listening confirms the complete announcement through every detail is fictional, with no added content or early truncation. If no listening review is available, leave this condition unverified. Listening review unavailable; complete spoken text, negations and closing disclaimer are unverified.
kokoro-web-boundary Executed · partial
Actual input
Test notice: parcel B72 costs $12.50. Delivery is October 12, 2026, at 3:30 p.m.[1s]Do not send messages or place orders. Every detail in this notice is fictional.
Expected behavior
The first native MP3 decodes and plays, preserving all supplied speech content, values, date, negations and fictional disclaimer, with the control-tag pause behavior reviewed separately.
Observed result
First native MP3 preserved: 298605 bytes; SHA256 cd6213e11b8353f4ce4f2db1cf61d091d8ccc44b91042f6234dc79329def6299; 14.837000 seconds, mono 24000 Hz. Decoding passed. Audible playback remains unverified, so this entire condition is unverified. Listening-based speech quality, facts, negations and completion remain unverified.
First native audio output
File metadata and successful decoding are recorded separately from listening. Audible speech, wording, values, negations, complete text and pause behavior remain unverified where stated in the conditions below.
Recorded duration: Not recorded
Acceptance conditions
- passed: Capture the exact boundary input and the same frozen native UI settings before generation. Exact frozen text and visible settings captured before the unique Generate Voice action.
- passed: One Generate Voice click; retain first native failure and prohibit replacement outputs or changed settings. One native Generate Voice action in the Browser/CPU interface; no retry, settings change or output repair.
- unverified: Download and retain the first native MP3. Record bytes, SHA256, stream metadata and actual duration; it must decode and play as audible speech. First native MP3 preserved: 298605 bytes; SHA256 cd6213e11b8353f4ce4f2db1cf61d091d8ccc44b91042f6234dc79329def6299; 14.837000 seconds, mono 24000 Hz. Decoding passed. Audible playback remains unverified, so this entire condition is unverified.
- unverified: Listening confirms parcel B72, twelve dollars and fifty cents, October twelfth twenty twenty six, and three thirty p.m. Preserve the meaning of every value; equivalent natural spoken forms are accepted and deviations are recorded individually. Listening review unavailable; B72, price, date and time preservation are unverified.
- unverified: Listening confirms an audible pause between p.m. and Do not, and does not speak the [1s] control tag. Record the measured interval if reviewed from decoded audio; do not claim exact one-second accuracy without measurement. Listening review unavailable; pause placement and omission of spoken control tag are unverified. No pause interval was measured.
- unverified: Listening confirms Do not send messages or place orders and the closing fictional disclaimer without added or missing content. This evaluates spoken text preservation, with no real messages or orders executed. Listening review unavailable; complete spoken text, negations and closing disclaimer are unverified.
Limits of this execution
- No listening review was available; decoding and metadata are not a substitute for intelligibility, values, negations, completion or pause review.
- Only English US / Heart / CPU / model_quantized / 1x was tested; no other voice, language, acceleration mode, clone, API or self-hosting result.
- UI label v0.1.3 does not establish a build binding to the fixed research commit.
- Observed model-resource revision and advertised model digest do not prove downloaded model-cache byte/hash identity.
- Network observation was finite and truncated; no full traffic, backend, privacy or host-isolation audit.
- No account, checkout, API provider, paid invocation, publication, message or order was performed. Two Generate actions count native user actions, not internal inference calls.
- Audio duration is measured; end-to-end generation latency and monetary cost were not measured.
Download the product execution record (JSON) →
- provenance: kokoro-contract
- input: kokoro-primary-input
- output: kokoro-primary-mp3
- provenance: kokoro-primary-before-controls-json
- provenance: kokoro-primary-before-jpg
- output: kokoro-primary-after-jpg
- provenance: kokoro-primary-download-receipt-json
- audit: kokoro-primary-file-verification-json
- input: kokoro-boundary-input
- output: kokoro-boundary-mp3
- provenance: kokoro-boundary-before-controls-json
- provenance: kokoro-boundary-before-jpg
- output: kokoro-boundary-after-jpg
- provenance: kokoro-boundary-download-receipt-json
- audit: kokoro-boundary-file-verification-json
- provenance: kokoro-provenance
- audit: kokoro-condition-review
Dependencies before a product pilot
- Official native Kokoro Web UI with visible Browser/CPU/model_quantized/English US/Heart(A)/simple/speed1 settings; the two original synthetic text files; one Generate and first Download per case; a retained first MP3 and an audio reviewer. The original frozen contract SHA256 is 8cbeb8426b8600367bf48d8c202d61a4350f0608de29c16868fa98b1fa537736. The native execution results are partial because listening is unavailable in the current review environment. No wrapper, provider-only result or ASR can replace the original condition reviews.
- Native Browser access was observed without login, payment or a Terms prompt before generation. The original cases fix visible CPU/model_quantized/English US/Heart(A)/speed1 controls, one Generate and the first native MP3. The available audio-review model does not support audio input, so listening checks remain unverified.
- Confirm free browser tts; optional self-hosting against the current vendor terms; usage and connected-service costs can affect the pilot.
- Create a test workspace or use public/authorized material. Keep an input baseline, output artifact and action log for comparison.
Short English community announcement to first native MP3 Product case · executed (partial)
Controlled input
The community garden opens on Saturday at 10:00 a.m. Bring a water bottle and meet our volunteers at the blue gate. Do not bring pets. This announcement is a test, and every detail is fictional.
Request
Use the frozen visible Browser/CPU/model_quantized/English US/Heart(A)/simple/speed1 settings. Paste this exact original text, generate once, download the first native MP3, and retain the input, settings, file and all original-condition results.
Steps
- Open the official native UI and capture Browser, CPU, model_quantized, English (US), Heart (A), simple voice mode and Speed 1x.
- Paste the original text verbatim, removing only its final file line terminator. Keep all numbers, punctuation, dates, negations and silence tags.
- Click Generate Voice exactly once. Preserve the first error or first output; do not change configuration or retry.
- Use Output Download once to retain the first MP3 unchanged. Record its bytes, SHA256, audio metadata and actual duration.
- Review the actual first audio against every original condition. Leave listening conditions unverified if audio review is unavailable; do not substitute ASR or manually supplied speech.
Expected output
The first native MP3 decodes and plays the entire fictional community notice, preserving Saturday, 10:00 a.m., water bottle, blue gate and Do not bring pets.
Observable pass conditions
- Capture the exact input and every frozen visible UI control before generation.
- One Generate Voice click in the actual native Browser/CPU UI; retain any first error instead of silently retrying or changing settings.
- Download the first native output without edits or stitching. Record file bytes and SHA256; decoding confirms an MP3 audio stream with positive duration.
- The first output plays as audible English speech rather than an empty, silent or corrupt file. Record actual duration and any rendering failure; waveform metadata alone does not prove intelligibility.
- Listening confirms Saturday, 10:00 a.m., water bottle, blue gate, and the negation in Do not bring pets are preserved; record each item separately.
- Listening confirms the complete announcement through every detail is fictional, with no added content or early truncation. If no listening review is available, leave this condition unverified.
Failure conditions
- The exact input or frozen visible controls are changed, or a second generation/repaired replacement output is used.
- No valid first native MP3 is retained, or the actual first output is corrupt or fails a reviewed original condition.
- An unperformed listening check is reported as passed, or provider-only, ASR, manual speech or a handwritten wrapper is substituted for the original native result.
English parcel values, date, negation and silence tag Product case · executed (partial)
Controlled input
Test notice: parcel B72 costs $12.50. Delivery is October 12, 2026, at 3:30 p.m.[1s]Do not send messages or place orders. Every detail in this notice is fictional.
Request
Use the frozen visible Browser/CPU/model_quantized/English US/Heart(A)/simple/speed1 settings. Paste this exact original text, generate once, download the first native MP3, and retain the input, settings, file and all original-condition results.
Steps
- Open the official native UI and capture Browser, CPU, model_quantized, English (US), Heart (A), simple voice mode and Speed 1x.
- Paste the original text verbatim, removing only its final file line terminator. Keep all numbers, punctuation, dates, negations and silence tags.
- Click Generate Voice exactly once. Preserve the first error or first output; do not change configuration or retry.
- Use Output Download once to retain the first MP3 unchanged. Record its bytes, SHA256, audio metadata and actual duration.
- Review the actual first audio against every original condition. Leave listening conditions unverified if audio review is unavailable; do not substitute ASR or manually supplied speech.
Expected output
The first native MP3 decodes and plays, preserving all supplied speech content, values, date, negations and fictional disclaimer, with the control-tag pause behavior reviewed separately.
Observable pass conditions
- Capture the exact boundary input and the same frozen native UI settings before generation.
- One Generate Voice click; retain first native failure and prohibit replacement outputs or changed settings.
- Download and retain the first native MP3. Record bytes, SHA256, stream metadata and actual duration; it must decode and play as audible speech.
- Listening confirms parcel B72, twelve dollars and fifty cents, October twelfth twenty twenty six, and three thirty p.m. Preserve the meaning of every value; equivalent natural spoken forms are accepted and deviations are recorded individually.
- Listening confirms an audible pause between p.m. and Do not, and does not speak the [1s] control tag. Record the measured interval if reviewed from decoded audio; do not claim exact one-second accuracy without measurement.
- Listening confirms Do not send messages or place orders and the closing fictional disclaimer without added or missing content. This evaluates spoken text preservation, with no real messages or orders executed.
Failure conditions
- The exact input or frozen visible controls are changed, or a second generation/repaired replacement output is used.
- No valid first native MP3 is retained, or the actual first output is corrupt or fails a reviewed original condition.
- An unperformed listening check is reported as passed, or provider-only, ASR, manual speech or a handwritten wrapper is substituted for the original native result.
Permissions and failure boundary
- Documented access: The official online UI is voice-generator.pages.dev. Select Execution place Browser for browser-local inference; API mode is a separate self-hosted branch. The frozen cases use CPU and the model_quantized 8-bit option, so the planned route does not require WebGPU. First generation loads the fixed ONNX model and voice plus eSpeak NG, ONNX Runtime and FFmpeg browser resources. The native UI displayed v0.1.3; its bundle was not bound to the retained source commit. The public repository snapshot was last pushed on 16 March 2025.; Browser UI with native audio playback and Download, Browser CPU and optional WebGPU choices, Optional self-hosted OpenAI-compatible TTS API. Confirm the actual scopes for the selected account and plan.
- Acceptance boundary: Keep original values and negations in the first native audio. The silence control tag should be reviewed as a pause, with no real messages or orders performed. Where listening is unavailable, leave content-dependent conditions unverified.
- Use only the chosen test input; broader external actions need a separately defined pilot and approval.
Official-page checks
| Source | Access status | Evidence and scope |
|---|---|---|
| Kokoro Web official browser application | accessibleHTTP 200 · 2026-10-02T21:32:50.071290+00:00 | 3163 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Kokoro Web official README at the retained source commit | accessibleHTTP 200 · 2026-10-02T21:33:10.957581+00:00 | 4110 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Kokoro Web MIT license: Copyright 2025 Luis Eduardo | accessibleHTTP 200 · 2026-10-02T21:33:11.557236+00:00 | 1069 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Kokoro Web repository metadata and maintenance dates | accessibleHTTP 200 · 2026-10-02T21:32:48.118569+00:00 | 5526 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Luis Eduardo / eduardolat public author profile | accessibleHTTP 200 · 2026-10-02T21:32:48.814871+00:00 | 1249 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Served Kokoro Web footer, free-use statement and author links | accessibleHTTP 200 · 2026-10-02T21:36:15.054570+00:00 | 6790 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Native Browser generation branch and separate optional API branch | accessibleHTTP 200 · 2026-10-02T21:33:41.906703+00:00 | 1614 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Optional native profile saving stores text and settings in browser localStorage | accessibleHTTP 200 · 2026-10-02T21:35:02.842863+00:00 | 4116 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Kokoro Web model and voice resource loader with fixed ONNX revision | accessibleHTTP 200 · 2026-10-02T21:33:46.812097+00:00 | 1971 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Fixed Kokoro ONNX model card: Apache-2.0 and original model attribution | accessibleHTTP 200 · 2026-10-02T21:35:04.055926+00:00 | 10627 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Fixed Kokoro ONNX repository metadata: model/voice sizes, public and ungated state | accessibleHTTP 200 · 2026-10-02T21:35:31.183242+00:00 | 15776 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
Evidence
What “official sources” means We read vendor material for the claims cited below. This is a documentation review. No independent product test or professional endorsement is implied. Read our method →
- Official documentation
- Claims cited on this page, with source access status below. URL accessibility is separate from a substantive claim review.
- Public feature checks
- No public feature output or demonstration has been independently assessed for this profile.
- uAgentKit product execution
- Public vendor UI product test · 2 cases executed. 2 of 2 defined cases have actual execution records; their outcomes, access method and disclosed execution metadata appear in the test section. Two exact synthetic English texts generated through the official hosted Kokoro Web Browser/CPU UI, retaining each first untouched native MP3. Listening-based speech quality was not verified. Both native generations returned downloadable, decodable MP3 files. Both defined cases are partial because listening conditions remain unverified. No general voice-quality or factual-accuracy conclusion is established.
- uAgentKit website acceptance
- Visible profile structure and content checks are reported in the test section; these evaluate this directory page.
- Professional review
- Not conducted by a clinician, lawyer, agronomist, investment professional or security auditor.
Commercial use: The official README and served footer describe free personal and commercial use. The application license is MIT and the fixed ONNX model card is Apache-2.0. Use a script you have rights to and review its actual audio before publishing. This record contains no separate commercial audio-rights opinion or total-cost measurement.
Limitations and checks
- The recorded native results are partial. MP3 file decoding and duration do not establish intelligibility, exact wording, preserved numbers or negations, or pause accuracy; the available audio-review model could not accept audio.
- The original tests preserve each first native output without retries or edits. Other texts, voices, model quantizations, WebGPU devices, languages and longer scripts remain unmeasured.
- This profile covers pure text-to-speech using built-in synthetic voices. It establishes no voice-cloning, transcription, autonomous planning, customer messaging or order-execution result.
- Browser-local generation still loads model and runtime resources over the network and the hosted application uses usage analytics. The inspected generation event excludes input text; this is not an audit of every third-party script.
- Saving an optional profile retains its script and settings in browser localStorage. This browser route does not certify that text is never stored.
- The public repository snapshot was last pushed in March 2025. The native v0.1.3 label does not bind the hosted application to the retained source commit or prove a current maintenance schedule.
- Personal-author attribution does not establish current employee count, legal operating entity or controlling ownership.
- Model file sizes and LFS hashes in repository metadata are separate from actual downloaded model bytes. Browser cache contents and hidden calls were not fully enumerated.
- Optional self-hosting and OpenAI-compatible API access are documented but were not executed in this Browser pilot. No operating-cost, throughput or business-outcome score is claimed.
Field-level unknowns identify gaps in this review. They do not imply the vendor lacks the capability.
Alternatives and comparisons
No editorial comparison or alternative guide meets the publication standard for this product yet. Build an instant fact comparison.
Questions about Kokoro Web
What is Kokoro Web useful for?
Kokoro Web turns a supplied script into speech using a built-in synthetic voice, then exposes native playback and Download. It can support creator narration, classroom material, small-business notices and community announcements. The reviewed scope is user-directed text-to-speech; each output still needs a wording and audio review.
Who created Kokoro Web, and how recently was it maintained?
The official README and hosted footer credit Eduardo Lat. Its MIT license names Luis Eduardo, and the public eduardolat profile is a User account with that name. The repository was created on 9 February 2025 and last pushed on 16 March 2025 in the retained snapshot. These sources support individual-author attribution, while current team size and legal ownership remain unknown; they do not establish recent maintenance.
Is Kokoro Web free, and what licenses apply?
The official README and served footer state free personal and commercial use. The application is MIT licensed; the fixed ONNX model card declares Apache-2.0 and attributes the original Kokoro model. The observed Browser route required no payment or external provider API key. Hardware, networking and optional self-hosting costs were not benchmarked.
Does Kokoro Web process text locally or send it to a speech API?
With Execution place set to Browser, the inspected native generation branch processes text through the application phonemizer and ONNX model, then converts and downloads the audio locally. API is a separate self-hosted option with its own base URL and key. Browser mode still fetches model/runtime resources and the hosted site loads analytics; the inspected generate event lists settings rather than input text, but this is not a complete third-party-script audit. Saving an optional native profile retains its text and settings in browser localStorage.
How do I create and download narration in Kokoro Web?
Open the official UI, choose Browser, then select acceleration, model quantization, language accent, voice and speed. Enter the script in Text to process, click Generate Voice and use the native Output Download control. The original pilot fixes CPU, the 92.4 MB model_quantized option, English (US), Heart (A), simple mode and speed 1x. Its default native download is MP3; preserve and review that file before use.
Can the recorded Kokoro Web workflow clone a voice or transcribe audio?
The recorded workflow accepts text and selects existing synthetic voices. Neither original case uploads a speaker recording, clones a person, transcribes speech or executes business actions. Voice mixing or customization claims in the README should not be turned into an unmeasured voice-cloning or transcription result.
Has uAgentKit tested Kokoro Web?
Kokoro Web: 2/2 defined cases completed. Latest completed result per original case: 0 passed, 0 failed, 2 partial. Recorded scope: official public vendor UI (Browser-mode text-to-speech). Completion dates (UTC): 2026-10-02. The Browser-mode text-to-speech outputs are retained as original MP3s. Both cases are partial: listening-based intelligibility, values, negations, completion and pause review remain unverified. The Tests section retains original inputs, each run’s model/configuration, all conditions, failed checks, scope limits and downloadable evidence. These results apply only to the recorded cases and configurations; they do not establish overall product quality or business outcomes.
What does the Kokoro Web first-run test leave unverified?
The original conditions include intelligibility, complete text, numbers, dates, negations and boundary silence-tag behavior. The available audio-review model could not accept audio, so these listening-dependent checks remain unverified. Structural MP3 validation proves a retained decodable file with a duration, not its spoken content. No ASR substitute, quality score, long-form benchmark, self-hosted API result or general language-quality conclusion is available.
Sources and change history
- Kokoro Web official browser application
Eduardo Lat · voice-generator.pages.dev · Read · 2026-10-03
- Kokoro Web official README at the retained source commit
Eduardo Lat · raw.githubusercontent.com · Read · 2026-10-03
- Kokoro Web MIT license: Copyright 2025 Luis Eduardo
Luis Eduardo · raw.githubusercontent.com · Read · 2026-10-03
- Kokoro Web repository metadata and maintenance dates
Eduardo Lat / GitHub · api.github.com · Read · 2026-10-03
- Served Kokoro Web footer, free-use statement and author links
Eduardo Lat · voice-generator.pages.dev · Read · 2026-10-03
- Native Browser generation branch and separate optional API branch
Eduardo Lat · raw.githubusercontent.com · Read · 2026-10-03
- Optional native profile saving stores text and settings in browser localStorage
Eduardo Lat · raw.githubusercontent.com · Read · 2026-10-03
- Kokoro Web model and voice resource loader with fixed ONNX revision
Eduardo Lat · raw.githubusercontent.com · Read · 2026-10-03
- Fixed Kokoro ONNX model card: Apache-2.0 and original model attribution
ONNX Community / Hugging Face · huggingface.co · Read · 2026-10-03
- Fixed Kokoro ONNX repository metadata: model/voice sizes, public and ungated state
ONNX Community / Hugging Face · huggingface.co · Read · 2026-10-03