 uAgentKit
Scribe OCR
Scribe OCR by Balearica extracts text from scans in your browser. Review two native label tests, original TXT/PDF exports, field errors and privacy boundaries.
Standard listing: the website button uses nofollow. Listing link policy.
On this page
What is Scribe OCR?
Scribe OCR is a specialist AI tool from Balearica for Document text extraction (OCR). Scribe OCR is Balearica's free open-source browser application for recognizing text in images and scanned documents, checking OCR against the original page, and exporting text or searchable PDFs. A person, creator or small shop can import a label, scan or PDF, run the built-in browser OCR, review quantities, dimensions, prices and missing fields, then download the result. The interface also supports editing existing OCR data and creating digital document versions. Balearica's public author profile explicitly names creation of scribeocr.com; current team size, legal operator and control remain unknown. Two original synthetic English labels were tested once each on 11 October 2026. The clear label passed all six conditions; the low-contrast rotated label failed exact SKU, price and searchable-PDF field checks because extra spaces split those values. Optional AWS Textract is a separate cloud mode with credentials and potential charges.
Best suited for
- People digitizing owned scans, creators proofreading print material, and small shops copying label facts into usable text while checking the original image. The built-in browser route suits users who want an editable OCR interface and native exports without configuring a cloud OCR account.
- A pilot focused on original english product-label png to unedited first native txt and searchable pdf, using owned or authorized PNG/JPEG document images or PDFs. Optional existing character-level Tesseract HOCR or Abbyy XML can be supplied for proofreading. The proposed pilot uses only two original synthetic English product-label PNGs; their exact-reference text files are evaluator-only and must not be imported as OCR data or ground truth.
Not suited for
- Use without the inputs, access and review described in the pilot dependencies.
- Two original label cases were executed once each. The clear label passed; the rotated low-contrast label failed exact SKU, price and PDF text checks. Normalized TXT character error was 0/219 and 3/244 respectively; these sample measurements are not general OCR accuracy.
- First native output, TXT/PDF exports, screenshots and fixed conditions are retained. The boundary PDF preserved the source image but split required text strings and raised parser syntax warnings; successful rendering alone does not prove a correct text layer.
Capabilities, with sources
- 01The official GUI README describes a free open-source web application for recognizing text, proofreading OCR data and creating digital documents.Official vendor statement · checked 2026-10-03Source ↗
- 02The official Getting Started page instructs users to import PNG/JPEG scans or a PDF, then use Recognize Text in the complete browser interface.Official vendor statement · checked 2026-10-03Source ↗
- 03The official FAQ describes built-in recognition as running locally in the browser and supports common Latin-script languages, with Simplified Chinese marked experimental.Official vendor statement · checked 2026-10-03Source ↗
- 04The native application exposes document import, word editing, layout controls and a Download menu with text and document formats.Official vendor statement · checked 2026-10-03Source ↗
- 05Balearica publicly identifies as the creator of scribeocr.com and links the same official application from the personal profile.Official vendor statement · checked 2026-10-03Source ↗
- 06The official GUI package names Balearica as author and AGPL-3.0 as its application license.Official vendor statement · checked 2026-10-03Source ↗
- 07The official Support page describes monthly snapshots and states that the application has no formal versions or releases.Official vendor statement · checked 2026-10-03Source ↗
- 08The retained native GUI source contains a separate optional AWS Textract branch with credential and charge-acceptance controls.Official vendor statement · checked 2026-10-03Source ↗
- 09The fixed language-loader source can read cached traineddata and fetch language resources from a CDN when no explicit path is supplied.Official vendor statement · checked 2026-10-03Source ↗
Inputs and outputs
Inputs
Owned or authorized PNG/JPEG document images or PDFs. Optional existing character-level Tesseract HOCR or Abbyy XML can be supplied for proofreading. The proposed pilot uses only two original synthetic English product-label PNGs; their exact-reference text files are evaluator-only and must not be imported as OCR data or ground truth.
Outputs
The documented native Download menu offers TXT, searchable PDF, HOCR, ALTO XML, DOCX, HTML, Markdown and Scribe document files; table XLSX is a separate optional feature. First native TXT and PDF exports from both original label cases are retained in the Tests section. The clear label passed; the low-contrast rotated label introduced spaces inside its SKU and two prices. Other formats remain untested.
Ecommerce & Retail fields
| Workflow stages | document ocr text extractionSource 1 |
|---|---|
| Output formats | The native menu lists TXT, PDF, HOCR, ALTO XML, DOCX, HTML, Markdown and Scribe documents. The test section retains first native TXT/PDF exports from two original labels; other export formats remain untested.Source 1 |
Fields awaiting verification · 6
These fields have no verified value in this profile. Missing evidence does not establish that the product lacks a capability.
| Commerce platforms | Not verifiedNot verified in the reviewed official material. |
|---|---|
| Integration by platform | Not verifiedNot verified in the reviewed official material. |
| Store data & permissions | Not verifiedNot verified in the reviewed official material. |
| Batch processing | Not verifiedNot verified in the reviewed official material. |
| Localization languages | Not verifiedNot verified in the reviewed official material. |
| Approval requirements | Not verifiedNot verified in the reviewed official material. |
Content Creators & Social Media fields
| Inputs | Owned or authorized PNG/JPEG document images or PDFs. Optional existing character-level Tesseract HOCR or Abbyy XML can be supplied for proofreading. The proposed pilot uses only two original synthetic English product-label PNGs; their exact-reference text files are evaluator-only and must not be imported as OCR data or ground truth.Source 1 |
|---|
Fields awaiting verification · 9
These fields have no verified value in this profile. Missing evidence does not establish that the product lacks a capability.
| Creator platforms | Not verifiedNot verified in the reviewed official material. |
|---|---|
| Content formats | Not verifiedNot verified in the reviewed official material. |
| Outputs | Not verifiedNot verified in the reviewed official material. |
| Aspect ratios | Not verifiedNot verified in the reviewed official material. |
| Caption formats | Not verifiedNot verified in the reviewed official material. |
| Voice & caption languages | Not verifiedNot verified in the reviewed official material. |
| Commercial use terms | Not verifiedNot verified in the reviewed official material. |
| Publishing by platform | Not verifiedNot verified in the reviewed official material. |
| Approval requirements | Not verifiedNot verified in the reviewed official material. |
A practical Scribe OCR workflow
The workflow and preparation text below retain the original Scribe OCR evaluation plan written before resource setup. Statements about resources not yet being prepared describe that earlier planning stage. Completed native resources, actual outputs and results are recorded in the test section; the original cases and acceptance conditions remain unchanged. View recorded results →
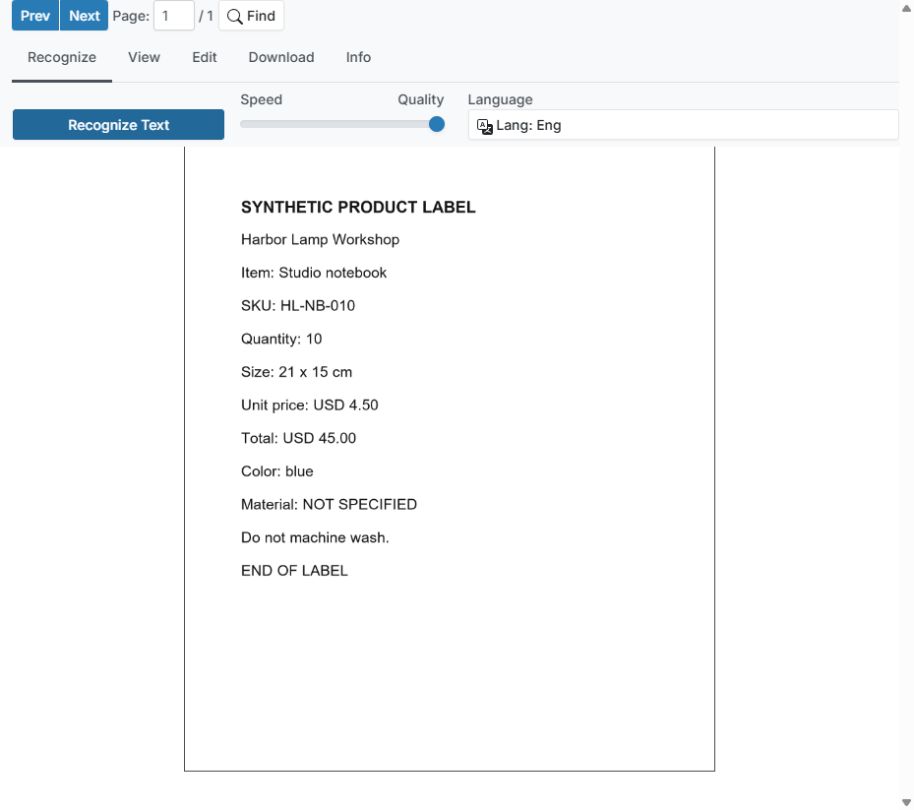
- Prepare the original english product-label png to unedited first native txt and searchable pdf fixture: SYNTHETIC PRODUCT LABEL Harbor Lamp Workshop Item: Studio notebook SKU: HL-NB-010 Quantity: 10 Size: 21 x 15 cm Unit price: USD 4.50 Total: USD 45.00 Color: blue Material: NOT SPECIFIED Do not machine wash. END OF LABEL
- Check Scribe OCR access through Complete browser UI with native document import and Download, Optional local HTTP hosting of the complete official application, Separate optional AWS Textract cloud adapter requiring user credentials and confirm the selected feature’s actual permissions.
- After the specific image-import permission is granted and the evaluation runtime is reviewed and frozen, import only the original PNG for this case into the complete native Scribe OCR UI. Keep English, basic Quality 1, Batch Mode off and Advanced Recognition off; preserve the first Recognize Text result without editing. Export the first native TXT and first native PDF from that result. Do not import this exact-reference text or any ground truth/OCR data.
- Inspect the unedited first native recognized result satisfies all six original condition definitions, with identity, values, missing information, negation, complete TXT and searchable PDF verified directly against the original PNG and evaluator-only reference. No product result currently exists. Compare it against the source input and retain the output/action log.
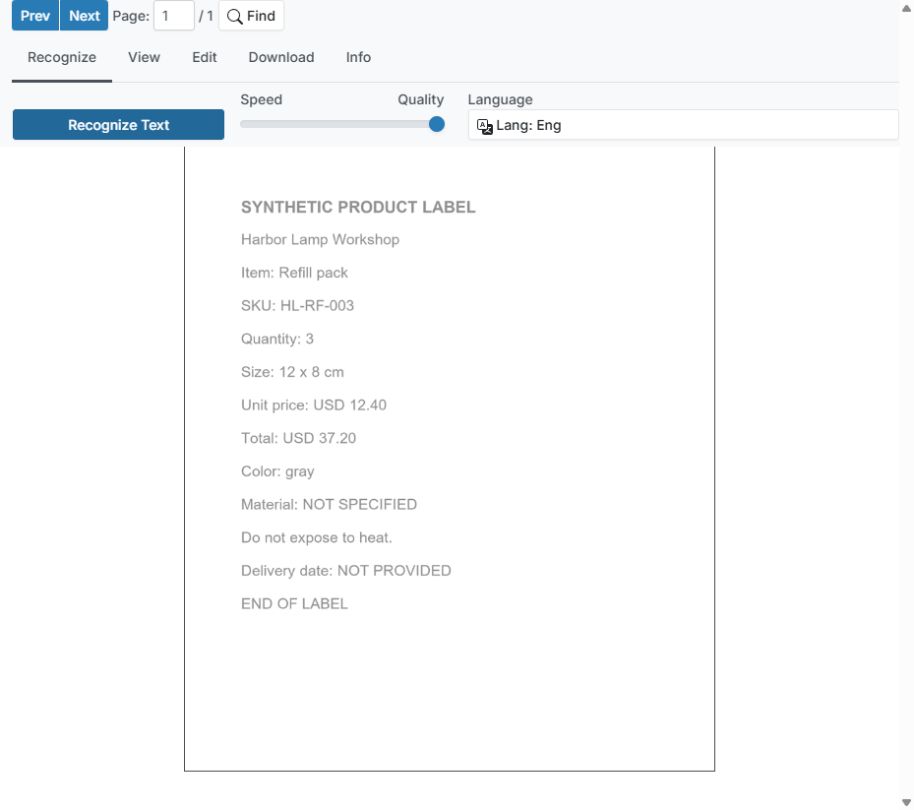
- Run the boundary case: SYNTHETIC PRODUCT LABEL Harbor Lamp Workshop Item: Refill pack SKU: HL-RF-003 Quantity: 3 Size: 12 x 8 cm Unit price: USD 12.40 Total: USD 37.20 Color: gray Material: NOT SPECIFIED Do not expose to heat. Delivery date: NOT PROVIDED END OF LABEL Accept the result only if all pass conditions are met and no failure condition occurs.
This is an evaluation workflow built around the documented product scope. Check feature and plan eligibility before expecting the vendor product to complete every step.
Setup and integrations
Use the full official web application at scribeocr.com. Official documentation also supports serving the complete repository through a local HTTP server; no desktop installation is provided in the retained README. Built-in recognition is described as browser-local, but code, WASM and language resources may load over the network. Optional AWS Textract sends recognition to its separate cloud route. The retained GUI source commit and Scribe.js gitlink are research references, not verified identities of the current hosted build or downloaded traineddata.. Documented access methods: Complete browser UI with native document import and Download, Optional local HTTP hosting of the complete official application, Separate optional AWS Textract cloud adapter requiring user credentials. Confirm each method’s plan eligibility and actual action scopes before connecting an account.
Access and setup steps
- Prepare a scan or document image you own or are authorized to process. Choose the document language and keep the original file available for checking recognized text.
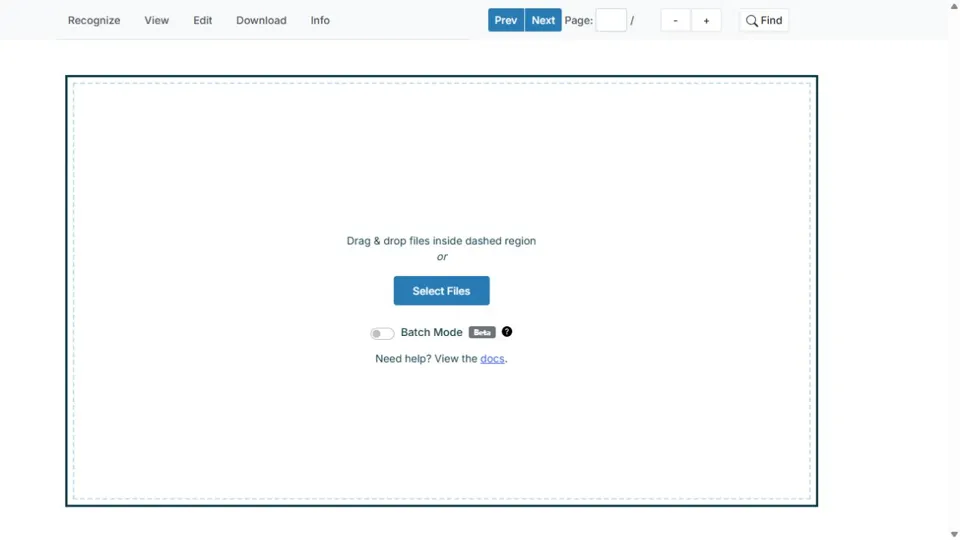
- Open the complete Scribe OCR application and use Select Files to import a PNG/JPEG scan or PDF. Optional existing HOCR or Abbyy XML is for proofreading existing OCR; it is separate from recognizing a new image.
- In the Recognize tab, select the document language and the built-in browser recognition options, then use Recognize Text. Review document orientation and available quality settings. Optional AWS Textract is a separate cloud mode with credentials and potential charges.
- Compare the recognized text with the original page, especially names, SKU strings, quantities, dimensions, prices, units, missing fields and negation. Save the original recognition before using word editing or proofreading controls to correct errors.
- Use the native Download menu to export the required format, such as TXT or a searchable PDF. Open the downloaded file and check complete text; a PDF should preserve the page image and have the searchable text layer you expect.
- For local hosting, follow the official instructions for the complete application and review its AGPL-3.0 license. Browser-local OCR may still load code, WASM and language resources over the network; review that boundary before processing sensitive documents.
Test access: public tool. On 11 October 2026, two original PNG labels were tested in the official native UI with English, Quality 1, Batch off, Advanced Recognition off, Auto-Rotate on and Optimize Fonts off. Each document received one Recognize Text click, with first TXT and PDF exports preserved. Clear label: passed. Low-contrast rotated label: failed. Hidden runtime and model identity remain unknown. Open the official access or installation page ↗
Pilot dependencies and unexecuted setup checks
Pilot dependencies
The workflow and preparation text below retain the original Scribe OCR evaluation plan written before resource setup. Statements about resources not yet being prepared describe that earlier planning stage. Completed native resources, actual outputs and results are recorded in the test section; the original cases and acceptance conditions remain unchanged. View recorded results →
- Specific two-PNG permission is pending. The original inputs and twelve acceptance conditions are frozen at input-and-acceptance contract SHA256 3eea51beea0b73b5060b24961bb77faa509715a7d9fddd259de91436c6c0b978; actual runtime remains unfrozen. Actual visible settings must be reviewed and frozen before recognition in this evaluation. Use the complete official UI with English/basic Quality 1/Batch off/Advanced off and the observed OCR Mode/Auto-Rotate on/Optimize Fonts off(disabled) preimport state. Hidden engine/model/build/segmentation/upscale/updateConfidence are unknown. Import only the PNG, never evaluator reference or existing OCR data. No account, paid cloud mode, AWS key or charge acceptance is part of the proposed pilot.
- On 11 October 2026, two original PNG labels were tested in the official native UI with English, Quality 1, Batch off, Advanced Recognition off, Auto-Rotate on and Optimize Fonts off. Each document received one Recognize Text click, with first TXT and PDF exports preserved. Clear label: passed. Low-contrast rotated label: failed. Hidden runtime and model identity remain unknown.
- Confirm free built-in browser ocr; optional cloud costs separate against the current vendor terms; usage and connected-service costs can affect the pilot.
- Create a test workspace or use public/authorized material. Keep an input baseline, output artifact and action log for comparison.
Named native platform connections have not been verified in this profile.
Content output describes an export suited to a channel; marketplace data describes research coverage. Exact data scopes and permissions need a setup review.
Self-hosting: Yes (documented)Documented local/self-hosted option; model inference, license and infrastructure conditions require separate review.Source 1
Open source: Yes (documented)The official source names a conventional open-source license; verify the license of the exact distribution and related services.Source 1
Integration fields awaiting verification
API: Not verifiedNot verified in the reviewed official material.
Pricing and additional costs
Free built-in browser OCR; optional cloud costs separate
The official README and documentation describe a free open-source application. The proposed pilot uses its built-in browser recognition, with no cloud credentials or checkout. Optional AWS Textract requires a user cloud account and explicit charge-risk acceptance; any cloud-provider charges are separate. Local hardware, electricity, networking and optional hosting costs were not measured.
Price details awaiting verification
Two original PNGs were imported and recognized in separate native documents without signing in or checkout. First TXT and PDF exports were retained. No AWS credentials or cloud mode were used. Per-run cash cost, resource use and network privacy were not measured; no zero-cost claim is inferred.
Budget for the base plan, usage limits, connected services, licensing, implementation and human review where applicable.
Pricing source ↗Recorded tests and results
Product-specific plan: The original cases were written for this product. Results cover only the recorded cases and configuration.
Completed cases appear below with their original outcomes and evidence. Unexecuted plans and access attempts are collapsed.
See the testing method and all product plans →
Actual public vendor UI product execution
Scribe OCR · Product version: Not disclosed · Native PNG recognition and first TXT/searchable PDF exports · 2026-10-11T05:53:32.240Z
Scope: Two original fixed synthetic cases, one first native execution per case; no general accuracy or full-feature claim.
Observed conclusion: Clear label passed all six conditions. Low-contrast rotated label failed exact SKU, price and searchable-PDF conditions despite normalized CER below 2%. First exports are retained unchanged.
Execution metadata, usage and audit scope
Model: Not disclosed; model tag: Not disclosed; digest: Not disclosed; inference runtime: Not disclosed; runtime version: Not disclosed.
Official entry: https://scribeocr.com/
Tested pages: https://scribeocr.com/ https://scribeocr.com/#
Observed UI settings: language: English; basicQuality: 1; batchMode: false; advancedRecognition: false; displayMode: OCR Mode (Image + Invisible Text); autoRotate: true; optimizeFonts: false; optimizeFontsDisabled: true; txtReflow: true; pdfStandardizePageSize: false; postExportDisplay: Boundary Ebook Mode screenshot only; original exports unchanged. These describe visible controls, not inferred model configuration.
Capture method and scope: Official browser UI only for product execution. Native screenshots and visible DOM retained; Scribe native downloads copied byte-for-byte and parsed offline. Original Goblin DOM text includes parent input before generated rows. No hidden API or alternate model used.
Authorized test scope: User requested continued single-agent tests and website evidence updates. Synthetic evaluation text/images only; no private documents, new accounts, purchases, sharing or expanded permissions.
Backend calls and hidden server actions were not observed. Browser metadata does not identify the vendor inference runtime.
Reported tokens: input not recorded, output not recorded. No usage source was recorded.
Measured cost: Not measured. Public native UI; no checkout or credentials used. Per-run cash cost, usage debit, electricity and network costs were not measured. Do not infer zero cost.
Audit: First native outputs independently checked against pre-execution frozen conditions by one research agent; no human reviewer.. Recorded read-access entries: 0; blocked-action entries: 0. Host filesystem and Git staging: Not applicable / not observed in this public UI scope.
Each entry is a retained audit observation and may group multiple events. Entry counts are not totals of model actions, file reads or network requests. The downloadable execution record retains the complete entries.
Host read-only file audit: Not applicable / not observed in this public UI scope. Any retained artifact hashes establish captured bytes only.
- One research agent, no sub-agents and no independent human or professional review. Two fixed synthetic samples do not establish overall accuracy or product ranking.
- First native results preserved; no manual repair, replacement input, changed engine or quality retry.
- Actual backend model/engine, version, digest, tokens, resource use, per-run cash cost and inference latency were not observed.
- Submission-to-observed-completion windows include browser/tool/polling delay; no model duration or speed comparison is claimed.
- Visible UI observations are not a backend, whole-page networking, privacy or host filesystem audit. No accounts, checkout, credentials, external messages, or expanded permissions were used.
Clear English label to first native TXT and searchable PDF Executed · passed
Actual input
Original synthetic PNG: /evidence/native-tools-2026-10-11/scribe-primary-input.png; SHA256 5df50de63499321ebd4a2a967ec32a05d6e228c339b4de5e4beb125b532f9e77. Exact reference retained for evaluator use only and never imported.
Expected behavior
The expectation below is the unchanged pre-execution plan. Its statement that no result existed describes the preparation date; the current result follows.
The unedited first native recognized result satisfies all six original condition definitions, with identity, values, missing information, negation, complete TXT and searchable PDF verified directly against the original PNG and evaluator-only reference. No product result currently exists.
Observed result
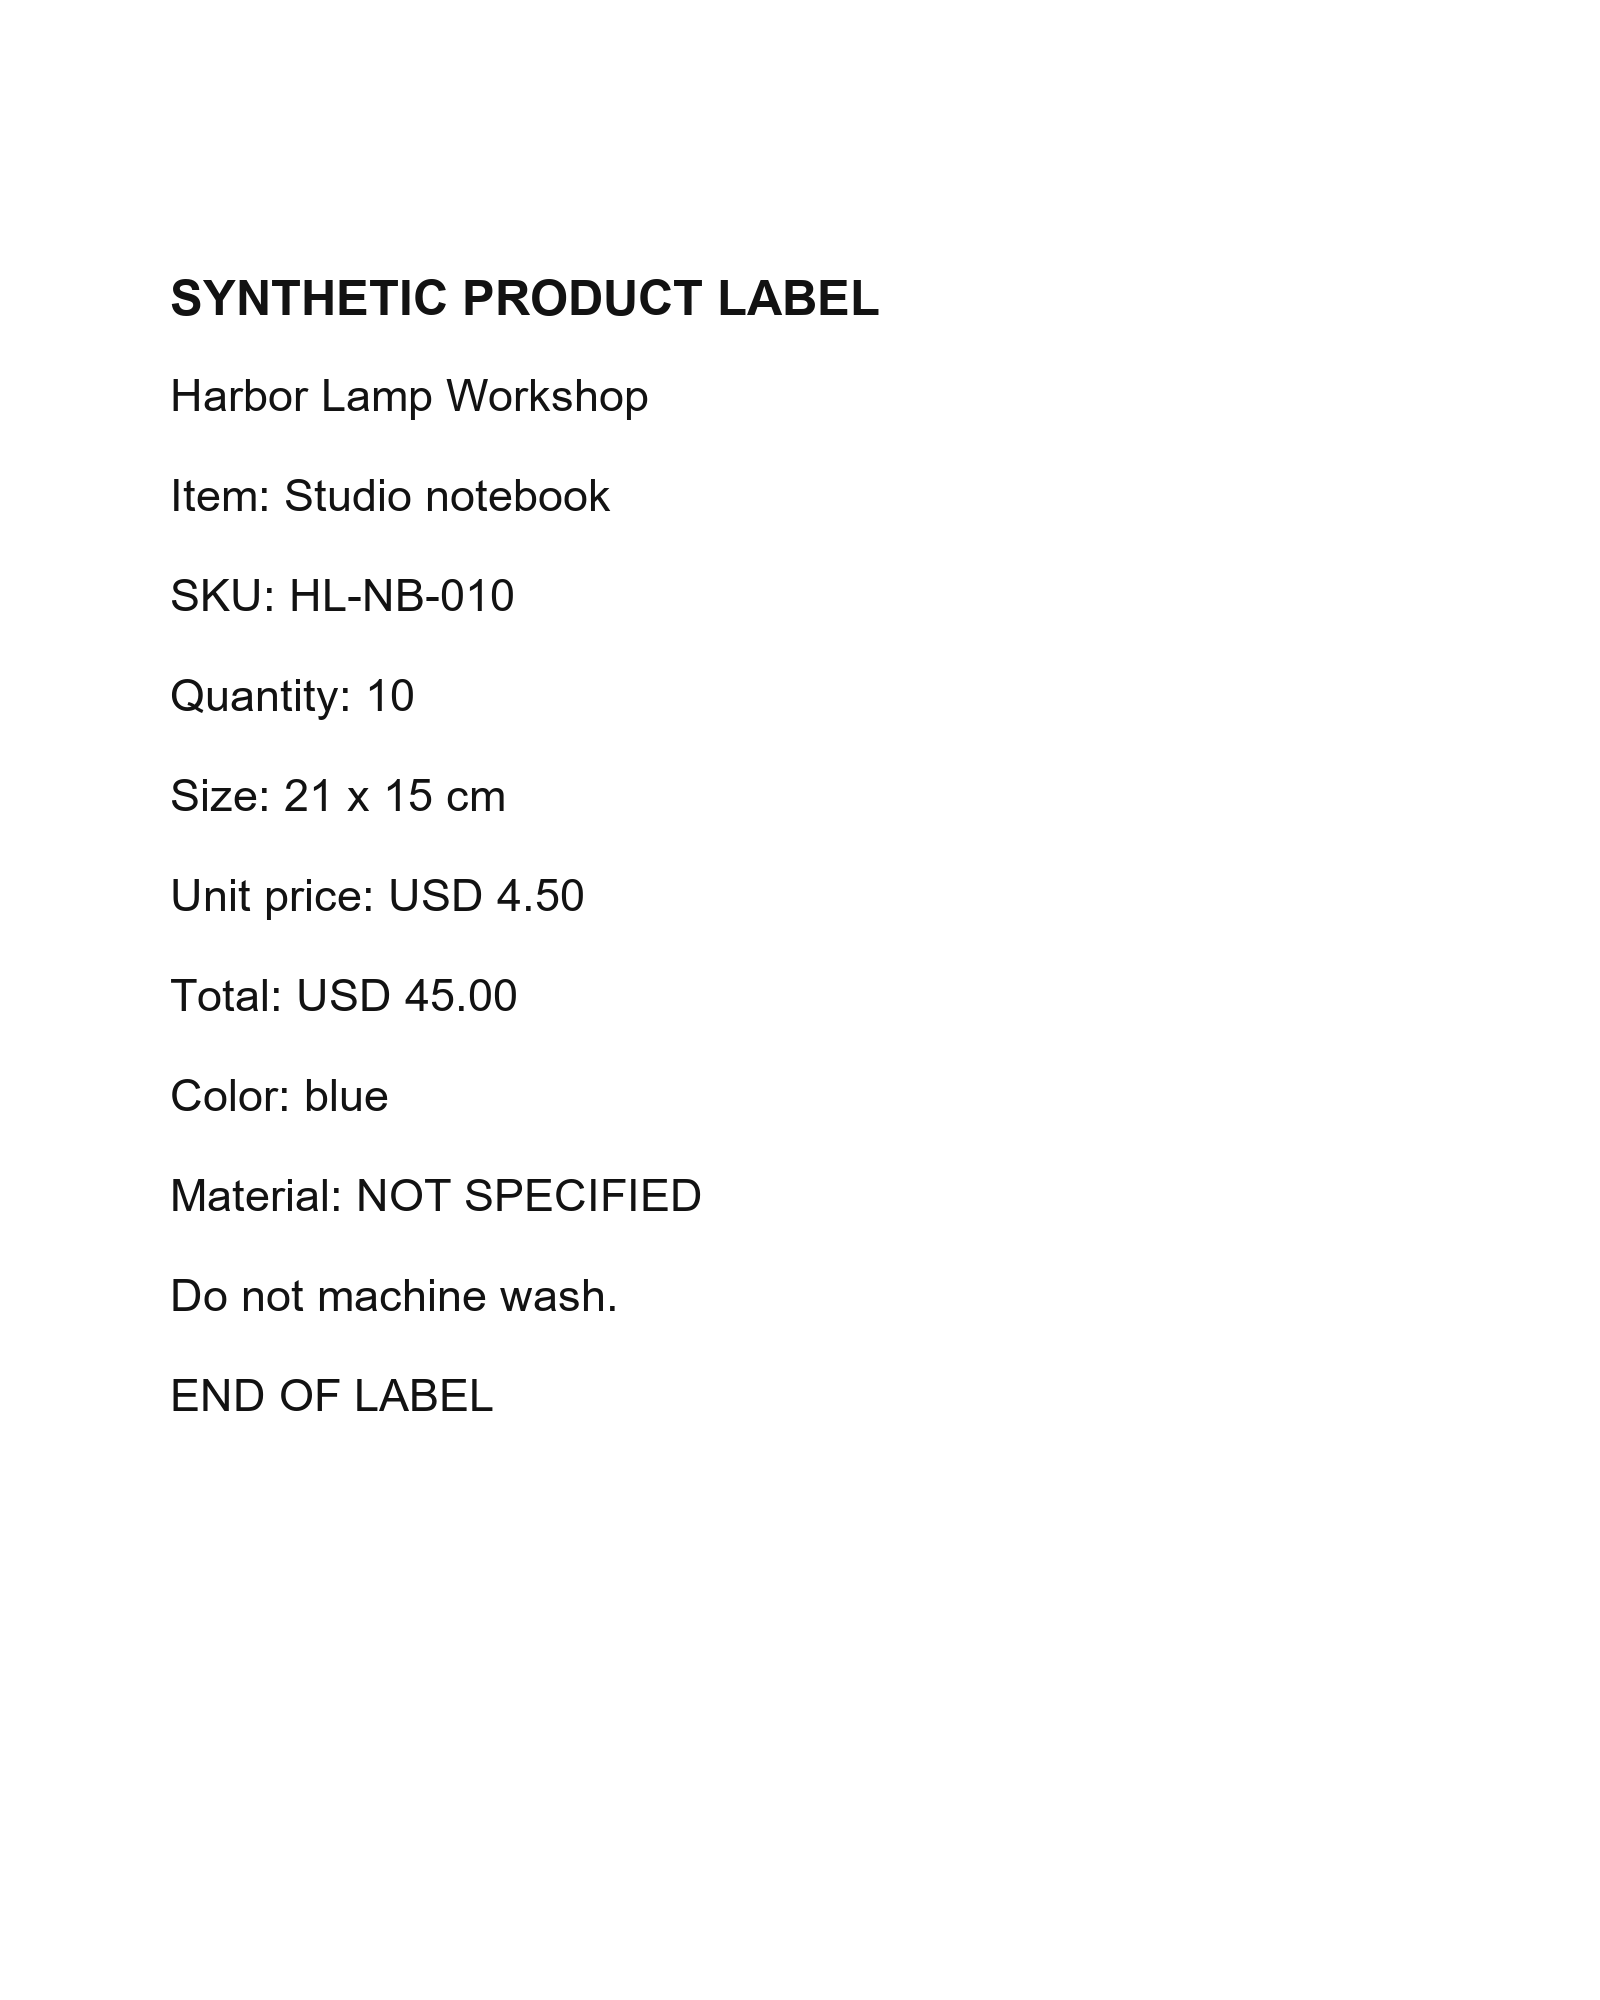
The clear original label passes six conditions: exact fields retained, normalized TXT CER 0/219, and a one-page searchable PDF preserving the source image.
Original response and native screenshots
Read the unedited first response
SYNTHETIC PRODUCT LABEL Harbor Lamp Workshop Item: Studio notebook
SKU: HL-NB-010 Quantity: 10 Size: 21 x 15 cm Unit price: USD 4.50 Total: USD 45.00
Color: blue
Material: NOT SPECIFIED
Do not machine wash.
END OF LABEL
Download the original response (TXT) →
Original expected-behavior review
passed: The clear original label passes six conditions: exact fields retained, normalized TXT CER 0/219, and a one-page searchable PDF preserving the source image.
Recorded duration: Not recorded
Acceptance conditions
- passed: Preserve every exact required string: ["Harbor Lamp Workshop", "Item: Studio notebook", "SKU: HL-NB-010"] All required case-sensitive strings are present in the unchanged first native TXT.
- passed: Preserve every exact required string: ["Quantity: 10", "Size: 21 x 15 cm"] All required case-sensitive strings are present in the unchanged first native TXT.
- passed: Preserve every exact required string: ["Unit price: USD 4.50", "Total: USD 45.00"] All required case-sensitive strings are present in the unchanged first native TXT.
- passed: Preserve every exact required string: ["Material: NOT SPECIFIED", "Do not machine wash."] All required case-sensitive strings are present in the unchanged first native TXT.
- passed: First native TXT exists, is nonempty UTF-8, is unchanged, contains END OF LABEL, and normalized CER <= 0.02 against the exact reference. Unchanged nonempty UTF-8 native TXT contains END OF LABEL. Normalized edit distance 0/219, CER 0.00000000, below 0.02. This does not override exact-field failures.
- passed: First native PDF parses as one page, opens with the original label image, and has extractable searchable text containing HL-NB-010, 45.00 and NOT SPECIFIED. No manual text addition or correction. One-page native PDF opens and renders; its embedded image decoded pixels match the source. All three required searchable strings are extractable. No parser warning was observed for this file.
Low-contrast rotated English label to first native TXT and searchable PDF Executed · failed
Actual input
Original synthetic PNG: /evidence/native-tools-2026-10-11/scribe-boundary-input.png; SHA256 bbb1bc922e8bb7ae3ea6a5e81a29abacf0fd20d532ce12e3d8df2bb21aaaa175. Exact reference retained for evaluator use only and never imported.
Expected behavior
The expectation below is the unchanged pre-execution plan. Its statement that no result existed describes the preparation date; the current result follows.
The unedited first native recognized result satisfies all six original condition definitions, with identity, values, missing information, negation, complete TXT and searchable PDF verified directly against the original PNG and evaluator-only reference. No product result currently exists.
Observed result
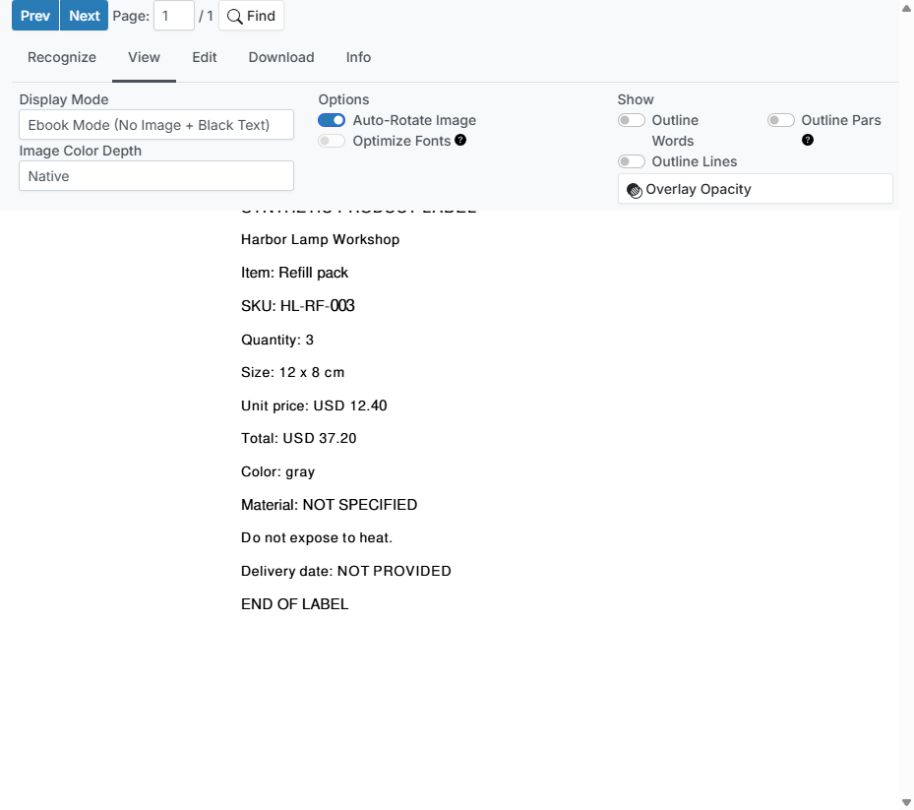
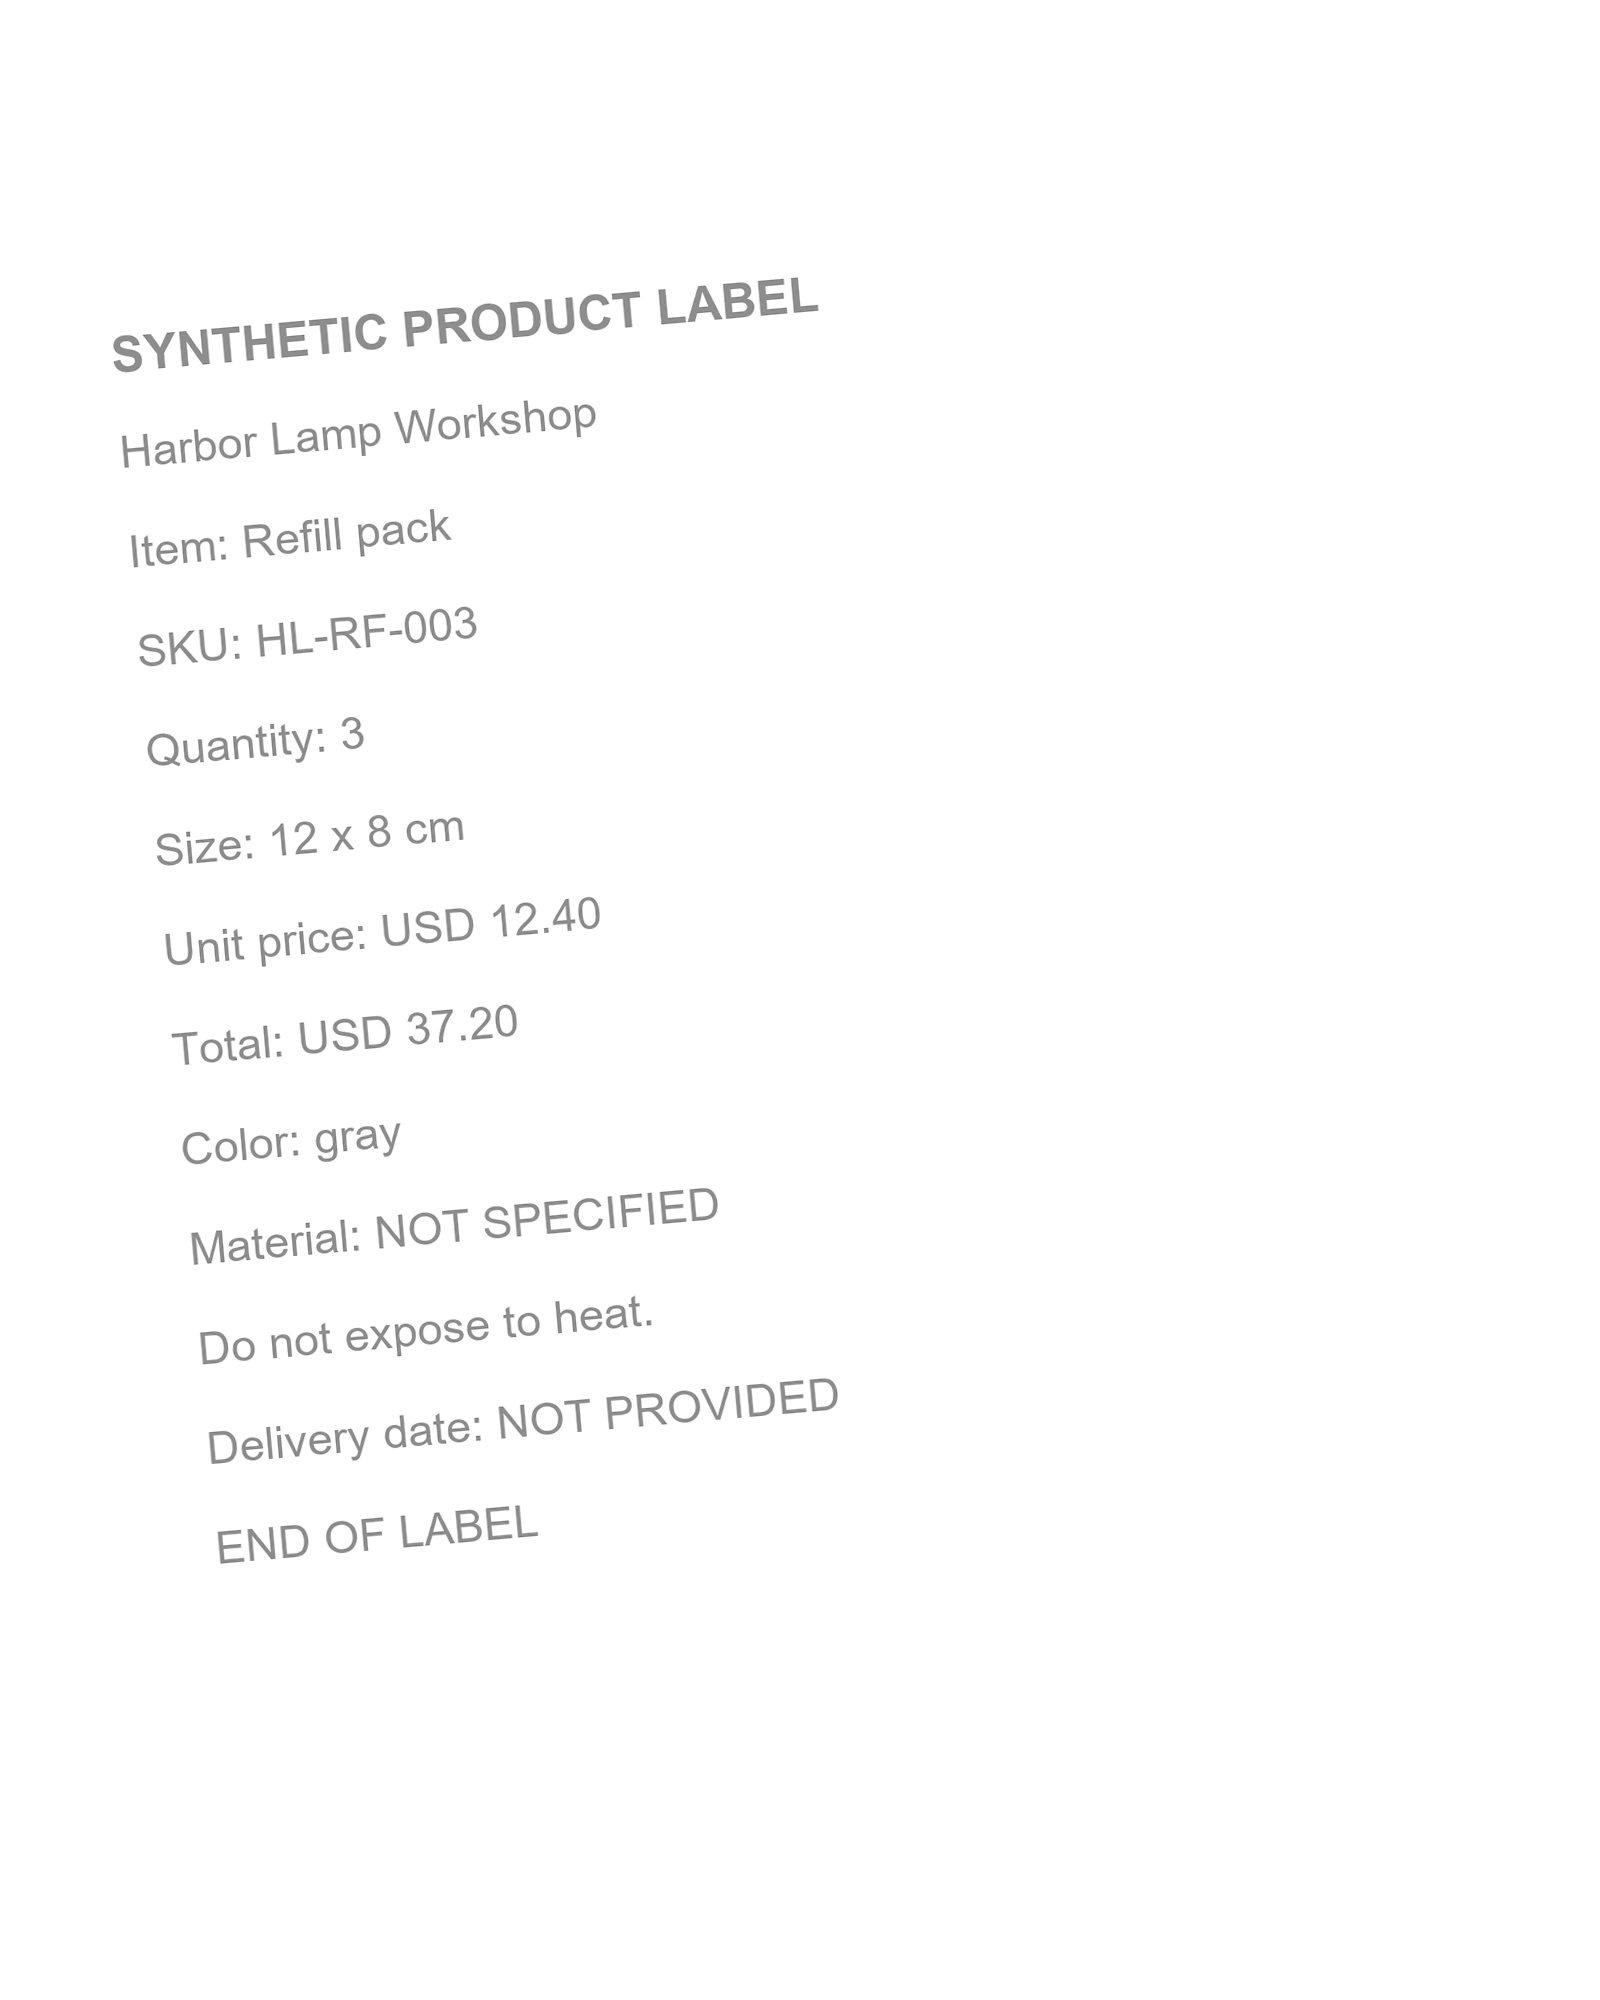
The low-contrast rotated label fails three of six conditions. TXT inserts spaces in HL-RF- 003, 12. 40 and 37.2 0; searchable PDF text repeats the splits. CER 3/244 (1.23%) passes the overall threshold, but exact SKU/price and PDF conditions fail. The image is preserved; PDF parser warnings also remain.
Original response and native screenshots
Read the unedited first response
SYNTHETIC PRODUCT LABEL Harbor Lamp Workshop Item: Refill pack SKU: HL-RF- 003 Quantity: 3
Size: 12 x 8 cm Unit price: USD 12. 40 Total: USD 37.2 0
Color: gray Material: NOT SPECIFIED Do not expose to heat. Delivery date: NOT PROVIDED END OF LABEL
Download the original response (TXT) →
Original expected-behavior review
failed: The low-contrast rotated label fails three of six conditions. TXT inserts spaces in HL-RF- 003, 12. 40 and 37.2 0; searchable PDF text repeats the splits. CER 3/244 (1.23%) passes the overall threshold, but exact SKU/price and PDF conditions fail. The image is preserved; PDF parser warnings also remain.
Recorded duration: Not recorded
Acceptance conditions
- failed: Preserve every exact required string: ["Harbor Lamp Workshop", "Item: Refill pack", "SKU: HL-RF-003"] Missing exact strings in the first native TXT: ["SKU: HL-RF-003"]. Extra spaces split these values; no manual normalization beyond the frozen whitespace rule was allowed.
- passed: Preserve every exact required string: ["Quantity: 3", "Size: 12 x 8 cm"] All required case-sensitive strings are present in the unchanged first native TXT.
- failed: Preserve every exact required string: ["Unit price: USD 12.40", "Total: USD 37.20"] Missing exact strings in the first native TXT: ["Unit price: USD 12.40", "Total: USD 37.20"]. Extra spaces split these values; no manual normalization beyond the frozen whitespace rule was allowed.
- passed: Preserve every exact required string: ["Material: NOT SPECIFIED", "Do not expose to heat.", "Delivery date: NOT PROVIDED"] All required case-sensitive strings are present in the unchanged first native TXT.
- passed: First native TXT exists, is nonempty UTF-8, is unchanged, contains END OF LABEL, and normalized CER <= 0.02 against the exact reference. Unchanged nonempty UTF-8 native TXT contains END OF LABEL. Normalized edit distance 3/244, CER 0.01229508, below 0.02. This does not override exact-field failures.
- failed: First native PDF parses as one page, opens with the original rotated label image, and has extractable searchable text containing HL-RF-003, 37.20 and NOT PROVIDED. No manual text addition or correction. One-page native PDF opens and renders; its embedded image decoded pixels match the source. Extracted text misses ["HL-RF-003", "37.20"] because of inserted spaces. Parser syntax warnings were retained; no repair or re-export.
Limits of this execution
- One research agent, no sub-agents and no independent human or professional review. Two fixed synthetic samples do not establish overall accuracy or product ranking.
- First native results preserved; no manual repair, replacement input, changed engine or quality retry.
- Actual backend model/engine, version, digest, tokens, resource use, per-run cash cost and inference latency were not observed.
- Submission-to-observed-completion windows include browser/tool/polling delay; no model duration or speed comparison is claimed.
- Visible UI observations are not a backend, whole-page networking, privacy or host filesystem audit. No accounts, checkout, credentials, external messages, or expanded permissions were used.
Download the product execution record (JSON) →
- input: frozen-protocol-json
- provenance: provenance-json
- audit: scribe-audit-json
- provenance: scribe-primary-timing-json
- input: scribe-primary-input-png
- input: scribe-primary-exact-reference-txt
- output: scribe-primary-first-txt
- output: scribe-primary-first-pdf
- provenance: scribe-primary-first-ax-txt
- audit: scribe-primary-pdf-extracted-txt
- output: scribe-primary-first-jpg
- provenance: scribe-boundary-timing-json
- input: scribe-boundary-input-png
- input: scribe-boundary-exact-reference-txt
- output: scribe-boundary-first-txt
- output: scribe-boundary-first-pdf
- provenance: scribe-boundary-first-ax-txt
- audit: scribe-boundary-pdf-extracted-txt
- output: scribe-boundary-first-jpg
- output: scribe-boundary-text-view-jpg
Test plans and preparation · 0 original cases unexecuted
The workflow and preparation text below retain the original Scribe OCR evaluation plan written before resource setup. Statements about resources not yet being prepared describe that earlier planning stage. Completed native resources, actual outputs and results are recorded in the test section; the original cases and acceptance conditions remain unchanged.
Dependencies before a product pilot
- Specific two-PNG permission is pending. The original inputs and twelve acceptance conditions are frozen at input-and-acceptance contract SHA256 3eea51beea0b73b5060b24961bb77faa509715a7d9fddd259de91436c6c0b978; actual runtime remains unfrozen. Actual visible settings must be reviewed and frozen before recognition in this evaluation. Use the complete official UI with English/basic Quality 1/Batch off/Advanced off and the observed OCR Mode/Auto-Rotate on/Optimize Fonts off(disabled) preimport state. Hidden engine/model/build/segmentation/upscale/updateConfidence are unknown. Import only the PNG, never evaluator reference or existing OCR data. No account, paid cloud mode, AWS key or charge acceptance is part of the proposed pilot.
- On 11 October 2026, two original PNG labels were tested in the official native UI with English, Quality 1, Batch off, Advanced Recognition off, Auto-Rotate on and Optimize Fonts off. Each document received one Recognize Text click, with first TXT and PDF exports preserved. Clear label: passed. Low-contrast rotated label: failed. Hidden runtime and model identity remain unknown.
- Confirm free built-in browser ocr; optional cloud costs separate against the current vendor terms; usage and connected-service costs can affect the pilot.
- Create a test workspace or use public/authorized material. Keep an input baseline, output artifact and action log for comparison.
Clear English label to first native TXT and searchable PDF Product case · executed (passed)
Controlled input
SYNTHETIC PRODUCT LABEL Harbor Lamp Workshop Item: Studio notebook SKU: HL-NB-010 Quantity: 10 Size: 21 x 15 cm Unit price: USD 4.50 Total: USD 45.00 Color: blue Material: NOT SPECIFIED Do not machine wash. END OF LABEL
Request
After the specific image-import permission is granted and the evaluation runtime is reviewed and frozen, import only the original PNG for this case into the complete native Scribe OCR UI. Keep English, basic Quality 1, Batch Mode off and Advanced Recognition off; preserve the first Recognize Text result without editing. Export the first native TXT and first native PDF from that result. Do not import this exact-reference text or any ground truth/OCR data.
Steps
- Use the complete official native web application. Create a fresh document using the native UI only; keep Batch Mode off.
- Import only the one prepared PNG product input for that case. Never import its exact-reference text or any other OCR data.
- Through native Recognize tab click Recognize Text exactly once for that case after settings/input are frozen. Do not use direct Scribe.js/Tesseract calls, console state, custom wrapper, hidden API or another OCR product.
- Retain the first completion or error and original displayed OCR before any manual correction. Native Combined mode can have internal multiple engine passes; one UI click is not a claim of exactly one internal inference.
- Using the same unedited first result, export the first native TXT and the first native PDF. Native export of the existing result is separate from recognition; no second recognition click or quality retry.
- Record downloaded bytes/hash/type and compare against evaluator-only reference after first-output preservation. Exported PDF must be parsed to establish searchable text; a PDF magic header alone is insufficient.
- If access/loading/output fails, retain the actual first failure. Do not change engine, contrast, input, scoring conditions or repeat recognition to obtain a pass.
Expected output
The unedited first native recognized result satisfies all six original condition definitions, with identity, values, missing information, negation, complete TXT and searchable PDF verified directly against the original PNG and evaluator-only reference. No product result currently exists.
Observable pass conditions
- Preserve every exact required string: ["Harbor Lamp Workshop", "Item: Studio notebook", "SKU: HL-NB-010"]
- Preserve every exact required string: ["Quantity: 10", "Size: 21 x 15 cm"]
- Preserve every exact required string: ["Unit price: USD 4.50", "Total: USD 45.00"]
- Preserve every exact required string: ["Material: NOT SPECIFIED", "Do not machine wash."]
- First native TXT exists, is nonempty UTF-8, is unchanged, contains END OF LABEL, and normalized CER <= 0.02 against the exact reference.
- First native PDF parses as one page, opens with the original label image, and has extractable searchable text containing HL-NB-010, 45.00 and NOT SPECIFIED. No manual text addition or correction.
Failure conditions
- AWS Textract or any cloud-adapter mode
- API keys
- Payment
- Account creation
- Batch Mode
- Ground truth import
- Manual OCR text repair before first result evidence
- Engine or input change after recognition
- Recognition retry for quality
- If access/loading/output fails, retain the actual first failure. Do not change engine, contrast, input, scoring conditions or repeat recognition to obtain a pass.
Low-contrast rotated English label to first native TXT and searchable PDF Product case · executed (failed)
Controlled input
SYNTHETIC PRODUCT LABEL Harbor Lamp Workshop Item: Refill pack SKU: HL-RF-003 Quantity: 3 Size: 12 x 8 cm Unit price: USD 12.40 Total: USD 37.20 Color: gray Material: NOT SPECIFIED Do not expose to heat. Delivery date: NOT PROVIDED END OF LABEL
Request
After the specific image-import permission is granted and the evaluation runtime is reviewed and frozen, import only the original PNG for this case into the complete native Scribe OCR UI. Keep English, basic Quality 1, Batch Mode off and Advanced Recognition off; preserve the first Recognize Text result without editing. Export the first native TXT and first native PDF from that result. Do not import this exact-reference text or any ground truth/OCR data.
Steps
- Use the complete official native web application. Create a fresh document using the native UI only; keep Batch Mode off.
- Import only the one prepared PNG product input for that case. Never import its exact-reference text or any other OCR data.
- Through native Recognize tab click Recognize Text exactly once for that case after settings/input are frozen. Do not use direct Scribe.js/Tesseract calls, console state, custom wrapper, hidden API or another OCR product.
- Retain the first completion or error and original displayed OCR before any manual correction. Native Combined mode can have internal multiple engine passes; one UI click is not a claim of exactly one internal inference.
- Using the same unedited first result, export the first native TXT and the first native PDF. Native export of the existing result is separate from recognition; no second recognition click or quality retry.
- Record downloaded bytes/hash/type and compare against evaluator-only reference after first-output preservation. Exported PDF must be parsed to establish searchable text; a PDF magic header alone is insufficient.
- If access/loading/output fails, retain the actual first failure. Do not change engine, contrast, input, scoring conditions or repeat recognition to obtain a pass.
Expected output
The unedited first native recognized result satisfies all six original condition definitions, with identity, values, missing information, negation, complete TXT and searchable PDF verified directly against the original PNG and evaluator-only reference. No product result currently exists.
Observable pass conditions
- Preserve every exact required string: ["Harbor Lamp Workshop", "Item: Refill pack", "SKU: HL-RF-003"]
- Preserve every exact required string: ["Quantity: 3", "Size: 12 x 8 cm"]
- Preserve every exact required string: ["Unit price: USD 12.40", "Total: USD 37.20"]
- Preserve every exact required string: ["Material: NOT SPECIFIED", "Do not expose to heat.", "Delivery date: NOT PROVIDED"]
- First native TXT exists, is nonempty UTF-8, is unchanged, contains END OF LABEL, and normalized CER <= 0.02 against the exact reference.
- First native PDF parses as one page, opens with the original rotated label image, and has extractable searchable text containing HL-RF-003, 37.20 and NOT PROVIDED. No manual text addition or correction.
Failure conditions
- AWS Textract or any cloud-adapter mode
- API keys
- Payment
- Account creation
- Batch Mode
- Ground truth import
- Manual OCR text repair before first result evidence
- Engine or input change after recognition
- Recognition retry for quality
- If access/loading/output fails, retain the actual first failure. Do not change engine, contrast, input, scoring conditions or repeat recognition to obtain a pass.
Permissions and failure boundary
- Documented access: Use the full official web application at scribeocr.com. Official documentation also supports serving the complete repository through a local HTTP server; no desktop installation is provided in the retained README. Built-in recognition is described as browser-local, but code, WASM and language resources may load over the network. Optional AWS Textract sends recognition to its separate cloud route. The retained GUI source commit and Scribe.js gitlink are research references, not verified identities of the current hosted build or downloaded traineddata.; Complete browser UI with native document import and Download, Optional local HTTP hosting of the complete official application, Separate optional AWS Textract cloud adapter requiring user credentials. Confirm the actual scopes for the selected account and plan.
- Acceptance boundary: Preserve every original field and negation in the first native recognition of the low-contrast rotated label. Missing data must remain represented by its exact source text. No manual repair, reference import, engine/input replacement or quality retry may turn a failed first result into a pass. These prepared conditions are unexecuted.
- Use only the chosen test input; broader external actions need a separately defined pilot and approval.
Source access and directory page checks
2 of 2 defined cases have actual product execution records. Inspect each outcome, access method, inputs and limits below.
Current HTTP/readability checks are listed below. They establish access, not the truth of every vendor claim.
Checked 2026-10-06T01:30:33.032Z. Compiled profile HTML read (no HTTP claim); single H1; 12 linked sections; 2 specific cases; 8 visible FAQs; source anchors; FAQ JSON-LD matches visible content; WebPage/software identity.
Official-page checks
| Source | Access status | Evidence and scope |
|---|---|---|
| Official Scribe OCR browser application | accessibleHTTP 200 · 2026-10-02T22:16:52.135427+00:00 | 139655 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Official Scribe.js library repository metadata | accessibleHTTP 200 · 2026-10-02T22:16:52.136429+00:00 | 6339 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Official Scribe.js README and supported complete GUI | accessibleHTTP 200 · 2026-10-02T22:16:52.139105+00:00 | 4661 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Official Scribe OCR GUI repository metadata | accessibleHTTP 200 · 2026-10-02T22:17:26.084685+00:00 | 6396 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Official Scribe OCR README: free browser application and local hosting | accessibleHTTP 200 · 2026-10-02T22:17:26.758282+00:00 | 4851 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Official GUI package: Balearica author and AGPL-3.0 | accessibleHTTP 200 · 2026-10-02T22:17:27.323760+00:00 | 1551 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Official getting started: import documents and recognize text | accessibleHTTP 200 · 2026-10-02T22:17:30.122681+00:00 | 12140 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Public Scribe OCR repository organization profile | accessibleHTTP 200 · 2026-10-02T22:17:31.069693+00:00 | 970 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Official language, local recognition, OCR editing and export FAQ | accessibleHTTP 200 · 2026-10-02T22:18:00.654486+00:00 | 23195 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Official support and monthly snapshot policy | accessibleHTTP 200 · 2026-10-02T22:18:01.321252+00:00 | 11815 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Official original-text editing and navigation controls | accessibleHTTP 200 · 2026-10-02T22:18:01.924937+00:00 | 17545 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Balearica public creator profile naming scribeocr.com creation | accessibleHTTP 200 · 2026-10-02T22:18:02.526630+00:00 | 1356 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Official retained GUI master commit and Scribe.js gitlink | accessibleHTTP 200 · 2026-10-02T22:18:03.125145+00:00 | 72664 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Official GUI AGPL-3.0 application license | accessibleHTTP 200 · 2026-10-02T22:18:03.867850+00:00 | 34523 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Fixed GUI source: native recognition/export and separate AWS branch | accessibleHTTP 200 · 2026-10-02T22:19:17.644735+00:00 | 100608 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Fixed Scribe.js source tree for retained GUI gitlink | accessibleHTTP 200 · 2026-10-02T22:19:18.714315+00:00 | 196539 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Fixed Scribe.js package metadata: 0.13.0 and AGPL-3.0 | accessibleHTTP 200 · 2026-10-02T22:19:19.481232+00:00 | 1748 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Fixed built-in browser Tesseract worker source | accessibleHTTP 200 · 2026-10-02T22:19:41.665127+00:00 | 9050 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
| Fixed language loader: cached traineddata and possible CDN reads | accessibleHTTP 200 · 2026-10-02T22:19:42.375238+00:00 | 32430 source bytes. Reused retained official-source GET bytes and receipt, verified against the research SHA256. Content length is original entity bytes. Source access and product performance are separate. |
Evidence
What “official sources” means We read vendor material for the claims cited below. This is a documentation review. No independent product test or professional endorsement is implied. Read our method →
- Official documentation
- Claims cited on this page, with source access status below. URL accessibility is separate from a substantive claim review.
- Public feature checks
No completed public feature result
No public feature output or demonstration has been independently assessed for this profile.- uAgentKit product execution
Public vendor UI product test · 2 cases executed
Public vendor UI product test · 2 cases executed. 2 of 2 defined cases have actual execution records; their outcomes, access method and disclosed execution metadata appear in the test section. Two original fixed synthetic cases, one first native execution per case; no general accuracy or full-feature claim. Clear label passed all six conditions. Low-contrast rotated label failed exact SKU, price and searchable-PDF conditions despite normalized CER below 2%. First exports are retained unchanged.- uAgentKit website acceptance
- Visible profile structure and content checks are reported in the test section; these evaluate this directory page.
- Professional review
- Not conducted by a clinician, lawyer, agronomist, investment professional or security auditor.
Commercial use: The reviewed application source declares AGPL-3.0. Use documents and images you have rights to process, and preserve their factual content and source rights when reusing exports. No separate hosted output-rights policy, blanket commercial clearance for all documents, or legal opinion was established; optional cloud-service terms and charges are separate from the built-in application.
Limitations and checks
- Two original label cases were executed once each. The clear label passed; the rotated low-contrast label failed exact SKU, price and PDF text checks. Normalized TXT character error was 0/219 and 3/244 respectively; these sample measurements are not general OCR accuracy.
- First native output, TXT/PDF exports, screenshots and fixed conditions are retained. The boundary PDF preserved the source image but split required text strings and raised parser syntax warnings; successful rendering alone does not prove a correct text layer.
- The two labels are original synthetic English text on clean backgrounds. Their high-contrast and low-contrast/rotated cases do not establish accuracy on real photos, handwriting, complex tables, long books or other languages.
- Numbers, units, SKU strings, negation and complete text need direct comparison with the source image. A native PDF file header does not establish a searchable text layer.
- Native proofreading can correct OCR errors, but a corrected export must not be reported as the unedited first recognition result. The proposed cases prohibit quality retries and replacement engines or inputs.
- Built-in browser processing can still require network resource downloads. The profile does not claim complete offline availability, zero whole-page external traffic or audited retention.
- AWS Textract is a separate optional cloud mode with credentials and potential charges. It is excluded from the local pilot and must not be described as the same privacy or price route.
- The repository/source gitlink, GUI package version and host behavior are different evidence scopes. No hosted commit or actual model digest is verified.
- Simplified Chinese support is experimental in the official FAQ. No language-quality, layout, multi-page or table-extraction benchmark was performed.
- Personal creator attribution does not prove current employee count, legal ownership or controlling structure. No autonomous planning, commerce update, messaging or order execution is established.
Field-level unknowns identify gaps in this review. They do not imply the vendor lacks the capability.
Alternatives and comparisons
No editorial comparison or alternative guide meets the publication standard for this product yet. Build an instant fact comparison.
Questions about Scribe OCR
What is Scribe OCR useful for?
Scribe OCR turns document images and scans into recognized text, lets a user proofread that text against the original image, and exports text or searchable document files. A person or small shop can use it to copy facts from an owned product label, while a creator can digitize print material. It is a user-directed OCR and document tool; no autonomous business or messaging workflow is established.
Who created Scribe OCR, and is its current team known?
The official GUI package names Balearica as author. The same public GitHub User profile explicitly says they created scribeocr.com and links the official app. That supports a personal creator origin. The real name, current team size, legal operator and controlling ownership were not established. The retained GUI repository was pushed on 28 September 2026 and its library on 1 October 2026; maintenance dates do not establish recognition quality.
Is Scribe OCR free, and does it require an account?
The official README and documentation describe the built-in browser application as free and open source. Two original PNG labels were imported, recognized and exported without login or checkout on 11 October 2026. No per-run cost or resource-use measurement was made. Optional AWS Textract requires cloud credentials and can incur separate charges; hardware, networking and hosting costs also differ from the free-software statement.
Does Scribe OCR process documents locally?
Official documentation describes built-in recognition as running locally in the browser. Code, WASM and language traineddata can still load over the network, and whole-page traffic, cache contents and retention were not independently audited. The current native application also exposes optional AWS Textract with separate credentials and a cloud-charge confirmation. That cloud branch is excluded from the proposed local tests and must not be covered by a blanket no-upload claim.
Which files can I import and export with Scribe OCR?
The official Getting Started guide supports PNG/JPEG document scans and PDFs. Existing character-level Tesseract HOCR or Abbyy XML can be imported for proofreading. The native Download menu lists TXT, PDF, HOCR, ALTO XML, DOCX, HTML, Markdown and Scribe documents; table XLSX is a separate optional feature. First native TXT and PDF exports from two labels are retained. Both PDFs have one page and preserve the original image pixels, but the boundary PDF text splits its SKU and amounts and emits parser syntax warnings. Other export formats were not tested.
How do I recognize text with Scribe OCR and preserve the original first output?
Open the complete official application, select the language and native recognition settings, import an authorized image, then click Recognize Text. Preserve the original first result before editing any words, and use native Download to retain TXT and PDF files from that same result. The proposed pilot keeps English, basic Quality 1, Batch Mode off and Advanced Recognition off. The observed public interface had Auto-Rotate on, Optimize Fonts off and disabled, and OCR Mode selected. Hidden model and engine details remain unknown. The two recorded cases used a settings and input contract frozen before recognition; each had one recognition click and no correction, input replacement or quality retry. References stayed outside the product.
Has uAgentKit tested Scribe OCR?
Scribe OCR: 2/2 defined cases completed. Latest completed result per original case: 1 passed, 1 failed, 0 partial. Recorded scope: official public vendor UI. Completion dates (UTC): 2026-10-11. Hidden backend calls and server actions were not observed in the public UI scope. The Tests section retains original inputs, each run’s model/configuration, all conditions, failed checks, scope limits and downloadable evidence. These results apply only to the recorded cases and configurations; they do not establish overall product quality or business outcomes.
What do the two planned Scribe OCR cases check?
The primary case uses a clear upright label; the boundary case uses gray text on white rotated five degrees. They check exact brand/item/SKU, quantity and dimensions, USD prices, missing material information and negation, complete first native TXT with character error rate at most 2%, and a first native PDF with a verifiable text layer. Exact-reference text is for the evaluator and must never be imported into the product. Both original cases have now been executed; their fixed conditions and historical plan remain available. The two results do not establish real-photo, handwriting, table, other-language, privacy or autonomous-action performance.
Sources and change history
- Official Scribe OCR browser application
Balearica / Scribe OCR · scribeocr.com · Read · 2026-10-03
- Official Scribe.js library repository metadata
Scribe OCR / GitHub · api.github.com · Read · 2026-10-03
- Official Scribe.js README and supported complete GUI
Scribe OCR · raw.githubusercontent.com · Read · 2026-10-03
- Official Scribe OCR GUI repository metadata
Scribe OCR / GitHub · api.github.com · Read · 2026-10-03
- Official Scribe OCR README: free browser application and local hosting
Scribe OCR · raw.githubusercontent.com · Read · 2026-10-03
- Official GUI package: Balearica author and AGPL-3.0
Scribe OCR · raw.githubusercontent.com · Read · 2026-10-03
- Official getting started: import documents and recognize text
Scribe OCR · docs.scribeocr.com · Read · 2026-10-03
- Public Scribe OCR repository organization profile
Scribe OCR / GitHub · api.github.com · Read · 2026-10-03
- Official language, local recognition, OCR editing and export FAQ
Scribe OCR · docs.scribeocr.com · Read · 2026-10-03
- Official support and monthly snapshot policy
Scribe OCR · docs.scribeocr.com · Read · 2026-10-03
- Official original-text editing and navigation controls
Scribe OCR · docs.scribeocr.com · Read · 2026-10-03
- Official retained GUI master commit and Scribe.js gitlink
Scribe OCR / GitHub · api.github.com · Read · 2026-10-03
- Official GUI AGPL-3.0 application license
Scribe OCR · raw.githubusercontent.com · Read · 2026-10-03
- Fixed GUI source: native recognition/export and separate AWS branch
Scribe OCR · raw.githubusercontent.com · Read · 2026-10-03
- Fixed Scribe.js source tree for retained GUI gitlink
Scribe OCR / GitHub · api.github.com · Read · 2026-10-03
- Fixed Scribe.js package metadata: 0.13.0 and AGPL-3.0
Scribe OCR · raw.githubusercontent.com · Read · 2026-10-03
- Fixed built-in browser Tesseract worker source
Scribe OCR · raw.githubusercontent.com · Read · 2026-10-03
- Fixed language loader: cached traineddata and possible CDN reads
Scribe OCR · raw.githubusercontent.com · Read · 2026-10-03